01
Niko1221/Strata
+4437 ★/day↗accelerating
A 125-billion-parameter model that normally needs a server, packed onto one gaming PC — NVIDIA card plus RAM plus SSD — writing answers faster than you can read.
A 125-billion-parameter model that normally needs a server, packed onto one gaming PC — NVIDIA card plus RAM plus SSD — writing answers faster than you can read.
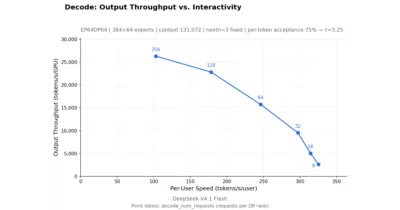
DeepInfer is the inference framework DeepSeek actually runs at scale, now released for offline use — kernels, parallelism tricks and all.
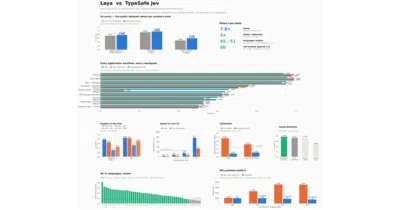
Laya exists to give multilingual documents a fast, deterministic decision layer without the latency and parsing drama of autoregressive models.
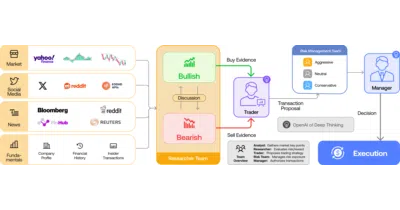
A research framework that assigns LLMs to trading-floor roles—analyst, researcher, trader, risk manager—to debate and execute simulated stock decisions.
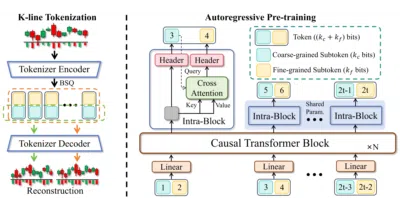
Kronos recasts noisy, multi-dimensional candlestick data as hierarchical discrete tokens so an autoregressive Transformer can forecast financial markets like a language model.
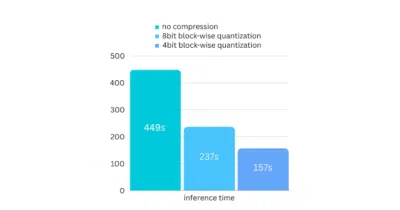
AirLLM slices giant transformers into layer shards so they fit in consumer VRAM without quantization or distillation.
It exists so you can download, run, and chat with open-weight LLMs locally through one CLI and REST API, keeping inference on your own silicon.
SGLang exists to push low-latency, high-throughput inference for LLMs and multimodal models from a single GPU up to massive clusters.
WeKnora exists to turn scattered enterprise documents into a queryable RAG, an autonomous reasoning agent, and a self-maintaining wiki.
It exists to run large language models on virtually any hardware—from Apple Silicon to RISC-V to your browser—with zero external dependencies and minimal setup.
It automates the removal of transformer safety alignment so you don't have to hand-tune abliteration parameters or pay for expensive post-training.
A Python framework for building production multi-agent systems that leans on LLM reasoning instead of rigid prompt choreography.
Because swapping from GPT-4o to Claude shouldn't require rewriting your request plumbing.
It teaches how LLMs work by implementing tokenization, attention, pretraining, and finetuning in pure PyTorch, one notebook at a time.
MiniMind is an educational training ground that rebuilds every stage of a modern language model—from tokenizer to RLHF—in raw PyTorch so you can see the gears turning instead of just calling high-level APIs.
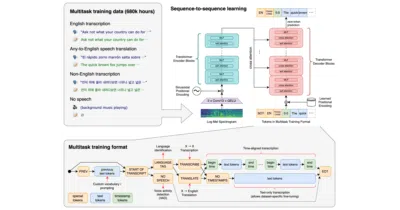
To give developers a single, general-purpose speech model that handles transcription, translation, and language identification by treating tasks as tokens to predict.
A hosted proxy that offers free, rate-limited API access to GPT, DeepSeek, and others for Chinese users who'd rather not tunnel through a VPN.
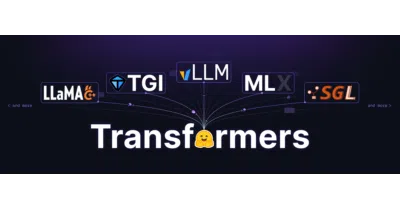
It centralizes model definitions so the same architecture works across PyTorch, JAX, vLLM, and llama.cpp without rewrites.
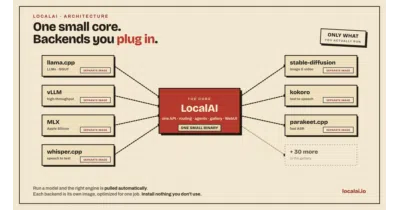
LocalAI wraps 36+ inference engines behind one OpenAI-compatible API and pulls them on demand, so you can run LLMs, vision, voice, and video on anything from a CPU to a Jetson.
To teach developers agent engineering from scratch using smolagents, LangGraph, and LlamaIndex, capped by an automated benchmark.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.