deepseek-ai/DeepInfer
DeepSeek open-sources the engine behind its own production serving
DeepInfer is the inference framework DeepSeek actually runs at scale, now released for offline use — kernels, parallelism tricks and all.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
DeepInfer is the high-performance inference framework that powers DeepSeek’s production services, released as an offline inference engine. It currently supports one model — DeepSeek-V4.1-Flash — and runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. It’s built on vLLM, with inspiration from SGLang and TensorRT-LLM, and the team credits all three.
The interesting bit
The feature list reads like a checklist of hard serving problems solved: batch-invariant inference (identical results regardless of how requests are batched), deterministic sampling, a zero-overhead asynchronous batch scheduler, and confidence-scheduled speculative verification where draft tokens are verified based on how confident the model is. There’s also SWA bounded replay, which cuts decoder prefill work by only replaying a bounded suffix of the context instead of the whole thing.
Key highlights
- Optimized kernels from the DeepSeek family: FlashMLA, DeepGEMM, DeepEP, TileKernels, plus custom TileLang kernels
- Parallelism via attention DP / balanced CP and MoE expert parallelism with EPLB
- DSpark speculative decoding with confidence-scheduled verification (draft length up to 5 by default)
- Structured outputs constrained by regex, JSON schema, or EBNF grammar
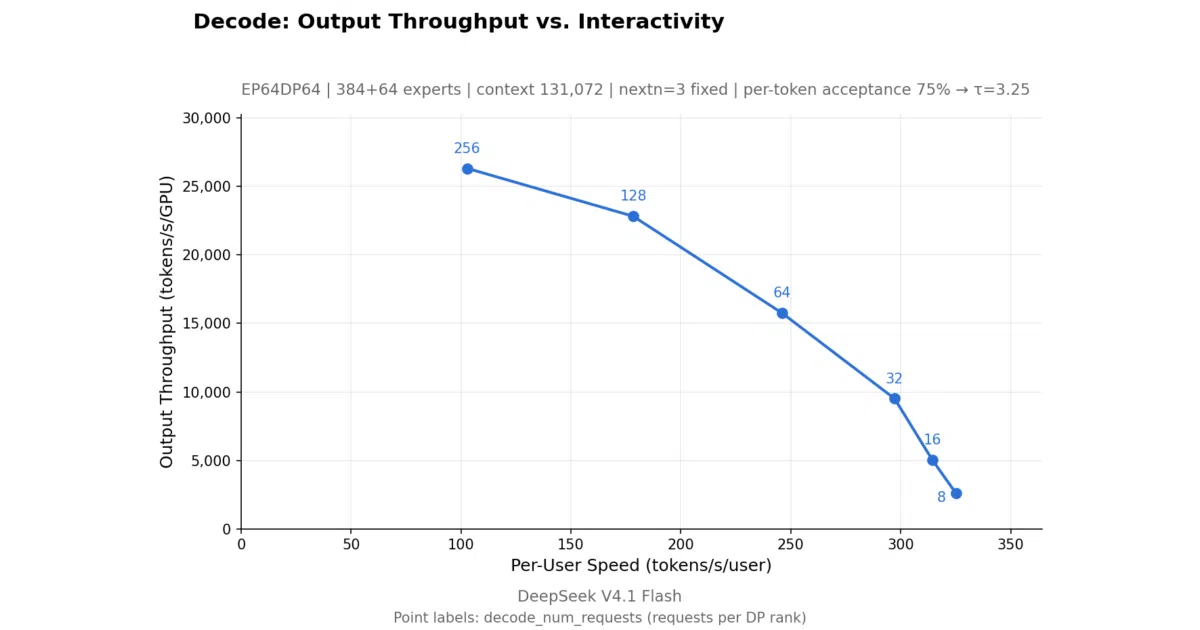
- Benchmarks included: prefill measured on 4 SM100 GPUs, decode on 64, with a reproduction sweep script
Caveats
- This is not a complete serving stack: KV cache management, prefill/decode disaggregation, and cross-replica load balancing are explicitly left out, though the README says most required engine functionality is implemented
- One model, two hardware targets — if you’re not running DeepSeek-V4.1-Flash on SM100 or Ascend 950, this isn’t for you
- Batch-invariant inference and deterministic sampling are NVIDIA-only
Verdict
Worth studying if you care about how frontier-lab serving engines are actually built — the parallelism and determinism details are the interesting part. If you wanted a drop-in serving solution for arbitrary models, this release stops short of that by design.
Frequently asked
- What is deepseek-ai/DeepInfer?
- DeepInfer is the inference framework DeepSeek actually runs at scale, now released for offline use — kernels, parallelism tricks and all.
- Is DeepInfer open source?
- Yes — deepseek-ai/DeepInfer is open source, released under the Apache-2.0 license.
- What language is DeepInfer written in?
- deepseek-ai/DeepInfer is primarily written in Python.
- How popular is DeepInfer?
- deepseek-ai/DeepInfer has 18k stars on GitHub.
- Where can I find DeepInfer?
- deepseek-ai/DeepInfer is on GitHub at https://github.com/deepseek-ai/DeepInfer.