01
Fractal-Compute-Orchestrations/FractalWorkspace
+69% /wk +577 ★/day↗accelerating
A workspace that pairs a Python federated-learning server with a Kotlin edge app so spare phones can train and even run LLM inference in parallel.
A workspace that pairs a Python federated-learning server with a Kotlin edge app so spare phones can train and even run LLM inference in parallel.
MOSS-Image is a compact open text-to-image model whose selling point is legible in-image text plus JSON layout control over where every word and object lands.
FractalCore schedules training tasks across mobile nodes, averages their checkpoints with FedAvg, and pays them in "Liquid MBs" — plus it slices Llama-class models into phone-sized pieces.
It replaces autoregressive LLM classification with a single parallel forward pass, cutting latency from seconds to sub-20 ms while staying local.
VisionHOPE is a PyTorch visual backbone built on self-referential nested learning, where what the model remembers and how it learns co-evolve while it processes a single image.
TrenTorch teaches machine learning by having you build a PyTorch-shaped framework from scratch, plus 350+ browser-graded coding questions.
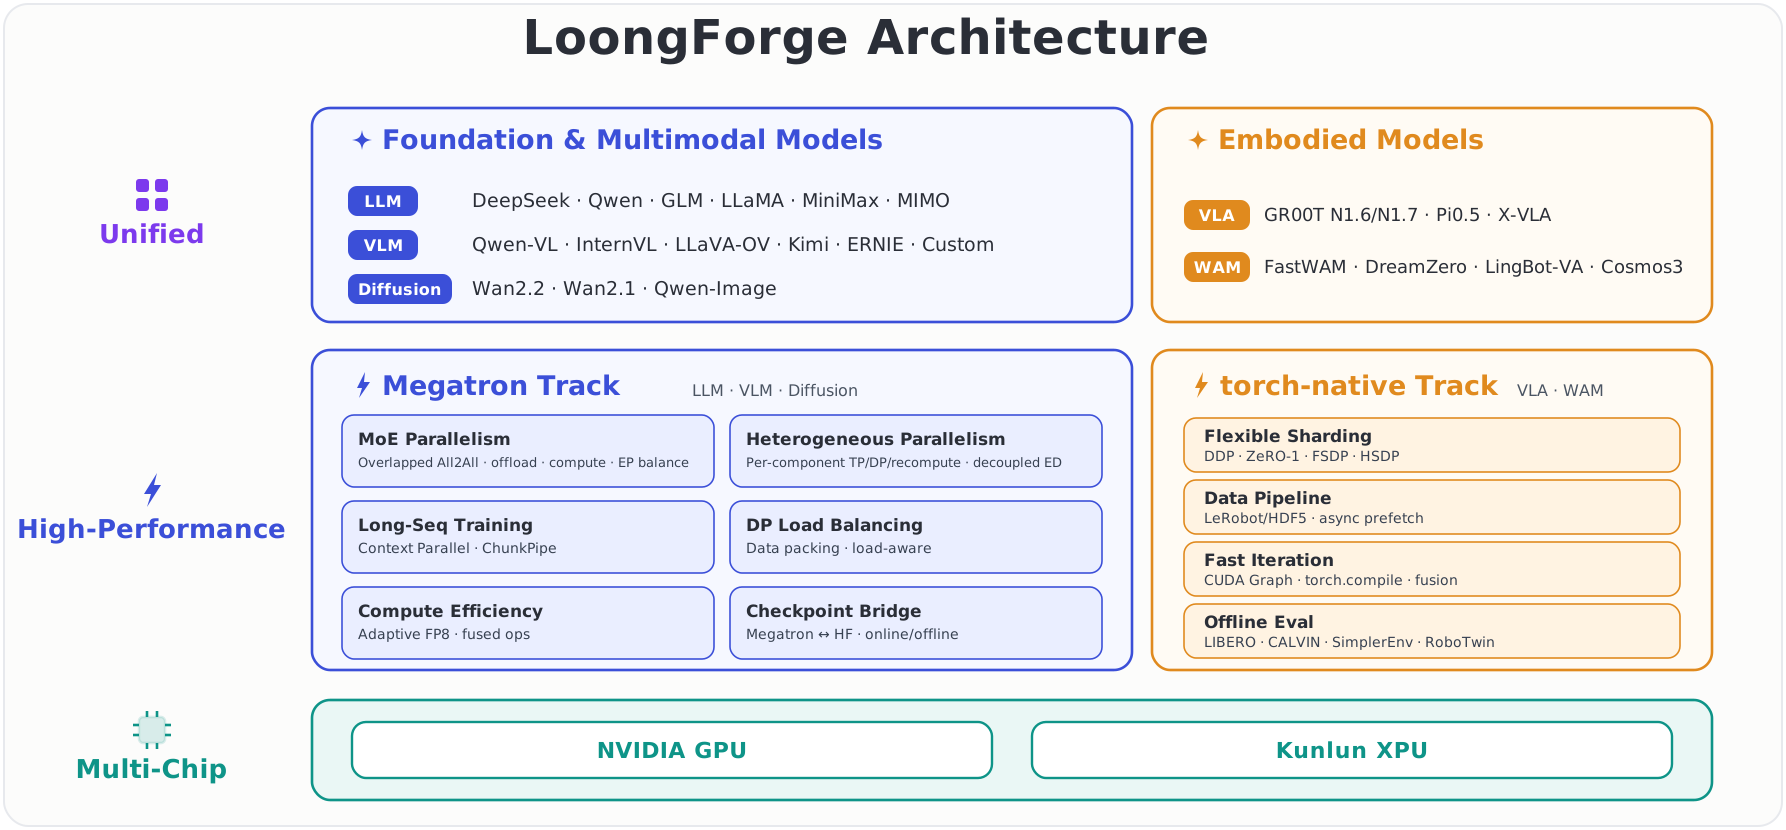
LoongForge is Baidu's unified training stack for language, vision, diffusion, and embodied models, open-sourced after serving production runs on thousands of XPUs and GPUs.
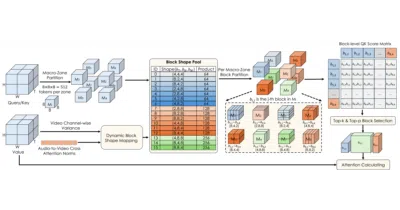
Prism rethinks attention structure for joint video-audio diffusion training, claiming 2.5x speedup over full attention at 2K resolution.
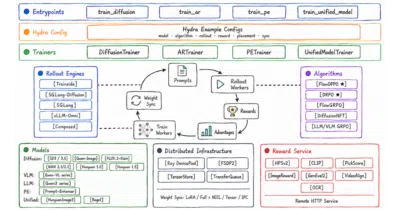
One framework to run RL post-training on diffusion, autoregressive, and hybrid models without rewriting the orchestration layer each time.
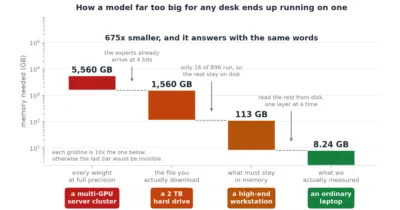
To prove that a 2.78-trillion-parameter model can run on a single CPU with 8 GB of RAM and no GPU.
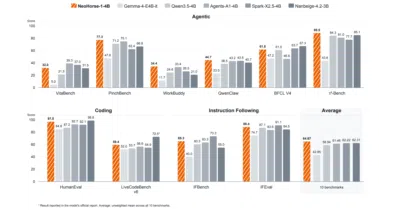
NeoHorse-1 prototypes a feedback loop where a routing harness evaluates agent trajectories and feeds capability-level signals back into the training mixture, aiming for recursive self-improvement.
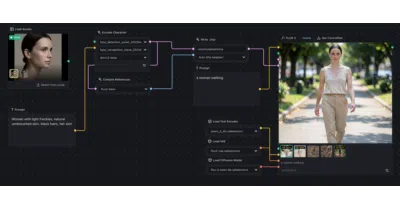
OmniChar Studio packages a character's face, body, and wardrobe into a portable `.char` file that stays consistent across models — and trains the LoRAs to back it up.
Handwired compiles ordinary JavaScript into matmuls and ReLUs — exact, differentiable, and untrained by design.
DanKS is Kingsoft’s attempt to master a four-player Chinese card game using structured retrieval and PPO self-play, shipped as a complete research lineage.
Fizgig trains LoRAs on 8 GB cards, but its real pitch is the workbench: repair, remix, and profile LoRAs you already have.
It exists because Persian TTS and linguistics tools need a modern, learned grapheme-to-phoneme converter that outputs standard IPA without brittle hand-written rules.
DiffusionOPSD closes the supervision gap in diffusion reward optimization by distilling explicit, continually refreshed targets from the model's own behavior policy.
Spirula Studio rebuilds the entire 3D Gaussian Splatting pipeline—video to splat to textured mesh—as a single C++ binary that runs on NVIDIA, AMD, Intel, and Apple GPUs via Vulkan, no Python required.
To house the code, checklists, and profiling recipes for an O’Reilly guide that treats AI performance as a full-stack systems problem rather than a benchmarking contest.
One pretrained model, seven chemical domains, no quantum mechanics degree required.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.