01
yi1108/printfilm
+76% /wk +752 ★/day↗accelerating
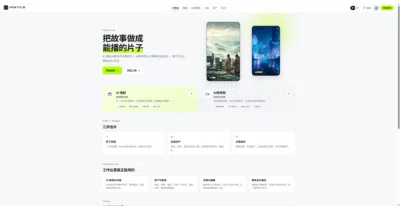
PRINTFILM exists so you can self-host a complete AI short-video factory—from script to voiced final cut—with user accounts, templates, and billing included.
PRINTFILM exists so you can self-host a complete AI short-video factory—from script to voiced final cut—with user accounts, templates, and billing included.
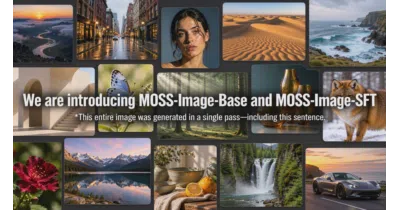
MOSS-Image is a compact open text-to-image model whose selling point is legible in-image text plus JSON layout control over where every word and object lands.
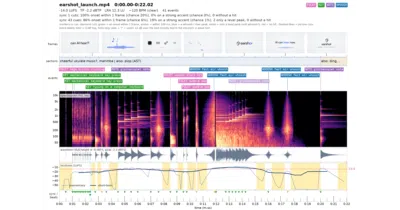
AI agents can render a whole launch film in code but can't hear it — earshot turns sound into evidence they can reason about, and critique, and even synthesize.
A compact DiT-based model that unifies text-to-image generation, transparent cutouts, and multi-reference editing under one 7B-parameter checkpoint.
This repo packages a Civitai author's exact prompt structure, LoRA settings, and a 136-pose 3D puppet library into an agent skill for Qwen-Image 2.1.
A Claude Code / Codex skill that automates the entire film pipeline, using Remotion to turn research and narration into deterministic 720p motion graphics with TTS voiceover.
gtrk is a CLI built for agent Skills: describe the edit you want, and it assembles a real, multi-track project you can keep refining.
A curated collection of Claude 5.5-made videos that obsessively separates what creators claim from what the evidence actually shows.
BeefTV is a local-first desktop workspace that treats AI as a collaborator on a free-form creative canvas rather than a button you click.
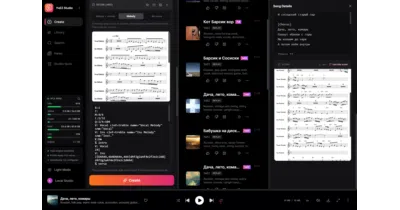
YuE2 Studio runs the open YuE2 song model locally on Windows and returns an editable score alongside the vocals — so you can change the performance without recomposing.
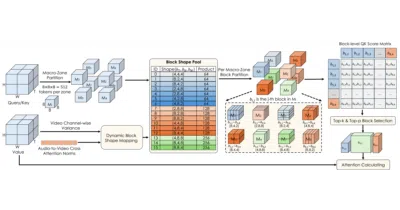
Prism rethinks attention structure for joint video-audio diffusion training, claiming 2.5x speedup over full attention at 2K resolution.
General image models produce logo-shaped pictures with nothing behind them; Inkloom is building a pipeline that constructs a mark as a sequence of explainable decisions — and says plainly that the generator is not live yet.
A verified prompt library for ByteDance's Seedance video generator, cross-checked against original posts and retested across models.
SparkDiffusion stacks sparse attention, low-rank approximation, and distillation to claim 200×+ faster video inference on Wan models.
It wires an infinite whiteboard directly into an AI film pipeline so solo creators can script, storyboard, generate, and rough-cut without tab-hopping.
yovoice bundles TTS, voice cloning, and full song generation into a native desktop app that never phones home or bills by the character.
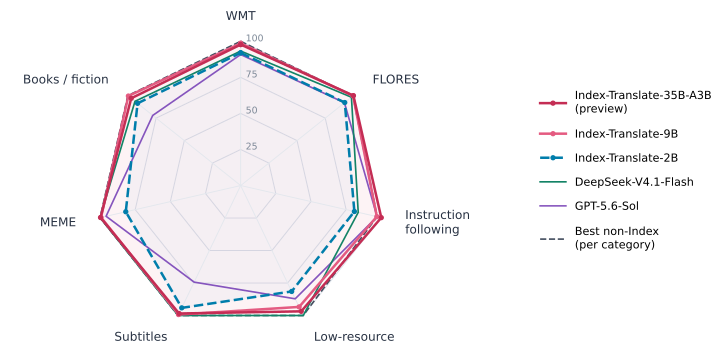
Index-Translate covers 150 languages, plus speech, dubbing, and whole-document translation — with a model that hits a target syllable count.
FreeVideo brings the MiniMax H3 video model to consumer GPUs by streaming weights and picking the right kernels for whatever card you happen to own.
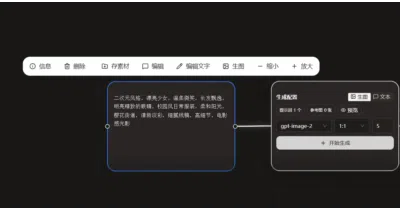
A self-hostable infinite canvas that wires AI image generation, reference editing, and chat into one collaborative workspace.
comfy-cli treats ComfyUI like the server software it is: installable, scriptable, and manageable from a terminal instead of a browser tab.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.