Tencent-Hunyuan/Prism
Sparse attention that trains video-audio models at 2K without the quadratic tax
Prism rethinks attention structure for joint video-audio diffusion training, claiming 2.5x speedup over full attention at 2K resolution.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
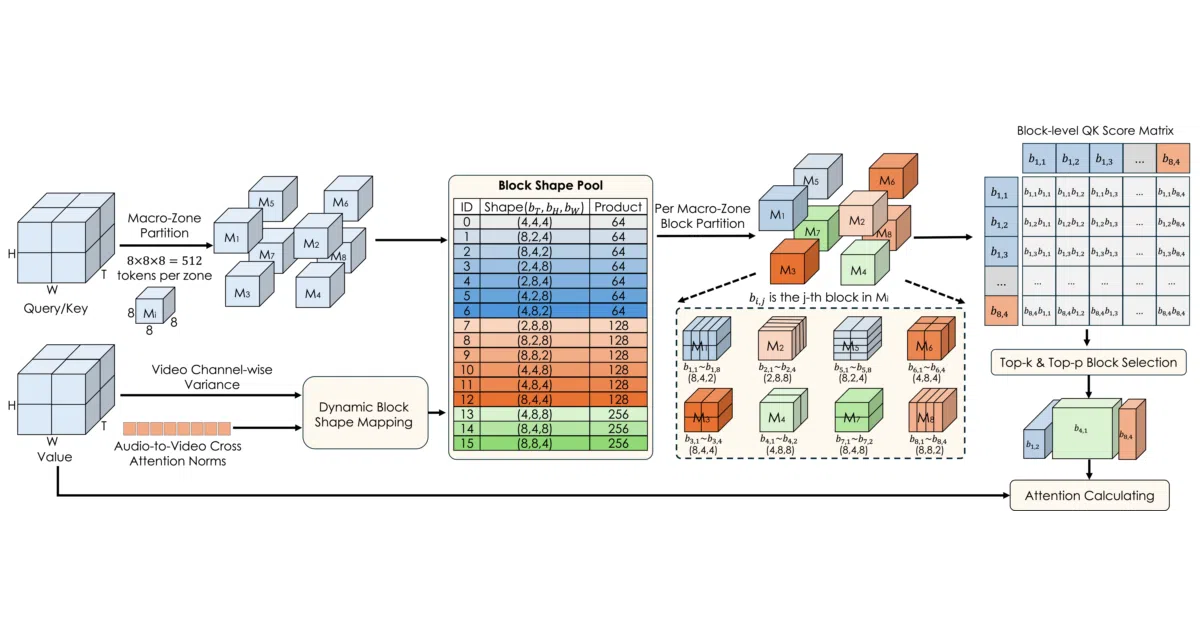
Prism is a dynamic sparse attention framework from Tencent Hunyuan, Fudan, and Zhejiang for natively training joint video-audio generation models at 720p, 1080p, and 2K. Rather than training at low resolution and upscaling, it trains directly at high resolution, where full attention becomes both expensive and noisy — quadratic cost plus attention spread over redundant tokens that dilutes the learning signal. The repo ships training, finetuning, inference, and data preprocessing code, plus two preview checkpoints (alpha and beta) on HuggingFace.
The interesting bit
The core idea is content-adaptive blocking. Prism splits the token sequence into spatiotemporal macro-zones, then uses two signals — video feature variance along the channel dimension, and feature norms from audio-to-video cross-attention — to decide where visual content changes fast and where audio strongly couples to specific visual regions. Zones get tailored block shapes: finer partitioning where things move or make sound, coarser where they don’t. The intuition that audio-visual interaction concentrates around sound-producing regions is what makes this more than generic sparse attention.
Key highlights
- Reports 2.5x training speedup over full attention while surpassing it in generation quality
- Hybrid block selection sets per-query sparsity dynamically rather than with a fixed mask
- Supports native joint video-audio generation and training at 720p, 1080p, and 2K
- Full pipeline included: latent extraction, multi-resolution/multi-duration bucketing, training, finetuning, inference
- Built on a MOVA-360p base model with WAN VAE latents
Caveats
- The “2.5x speedup” and quality claims come from the authors’ paper; no independent reproduction is available yet
- Hardware bar is steep — CUDA ≥ 12.4, FlashAttention, and FSDP sharding recommended for 1080p/2K inference
- “Prism-pro” is still on the to-do list; what’s released are preview checkpoints
Verdict
Worth a close look if you train or research multimodal diffusion models and keep hitting the attention wall at high resolution. If you just want a text-to-video toy, the preview checkpoints are interesting but this is fundamentally a research codebase for people who read the paper.
Frequently asked
- What is Tencent-Hunyuan/Prism?
- Prism rethinks attention structure for joint video-audio diffusion training, claiming 2.5x speedup over full attention at 2K resolution.
- Is Prism open source?
- Yes — Tencent-Hunyuan/Prism is an open-source project tracked on heatdrop.
- What language is Prism written in?
- Tencent-Hunyuan/Prism is primarily written in Python.
- How popular is Prism?
- Tencent-Hunyuan/Prism has 684 stars on GitHub.
- Where can I find Prism?
- Tencent-Hunyuan/Prism is on GitHub at https://github.com/Tencent-Hunyuan/Prism.