01
cosmo-wander-ai/cosmo-edge
+27% /wk +35 ★/day↗accelerating
It packages a C++17 video analytics runtime, a browser-based pipeline editor, and async VLM nodes into a single deployable appliance stack for edge hardware.
It packages a C++17 video analytics runtime, a browser-based pipeline editor, and async VLM nodes into a single deployable appliance stack for edge hardware.
A Flask dashboard and Android client that repurpose e-waste into a privacy-first computer-vision pipeline with structured event logging.
This plugin wires an upstream vision toolkit into DeepSeek Harness so text-only models can inspect images, locate UI elements, and diff screenshots without swapping LLMs.
It wraps Tesseract and OpenAI-compatible LLMs into a single toolkit for turning receipt images into raw text or structured JSON.
A transformer-based object detector that claims to beat YOLO at its own real-time game, with official Paddle and PyTorch implementations.
RF-DETR is Roboflow’s bet that a DINOv2 transformer backbone can finally beat YOLO on both speed and accuracy in real-world detection and segmentation tasks.
CompreFace wraps FaceNet and InsightFace in a Dockerized REST API so developers can add face recognition, verification, and detection to apps without building ML pipelines.
A curated index of hands-on machine learning, generative AI, and data-science projects, with about a third marked as end-to-end builds.
A vision model that counts anything you can describe, from cattle to cancer cells, by placing a point on every instance.
It reconstructs 3D scenes from streaming video in real time without per-scene optimization, using a feed-forward transformer that remembers trajectory and corrects drift as it goes.
A self-hosted NVR that runs object detection, face recognition, and motion alerts entirely on local hardware.
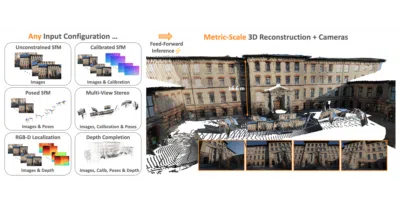
MapAnything turns a grab bag of inputs—images, poses, depth, calibration—into metric 3D geometry with a single feed-forward pass.
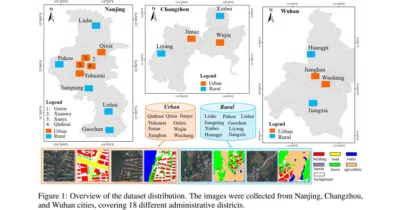
A land-cover dataset built to stress-test whether segmentation models trained on cities survive the countryside.
A free Android image editor that packs dozens of tools—from basic crops to OCR, EXIF editing, and AI upscaling—into one open-source package.
UNet++ redesigns skip connections into dense, nested pathways so medical image segmentation no longer depends on guessing the perfect U-Net depth.
CVAT is the self-hosted annotation workbench that lets teams draw bounding boxes, polygons, and 3D cuboids on their own hardware while plugging in their own models to do the boring parts.
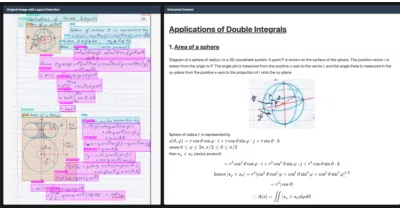
It converts images and PDFs into structured HTML, Markdown, or JSON while reconstructing tables, forms, and handwriting that most OCR tools reduce to plain text soup.
FiftyOne exists because model performance is usually a data problem, and staring at raw image folders doesn't scale.
DeepCamera turns dumb security cameras into locally-run AI agents that can see, remember, and text you back via Telegram.
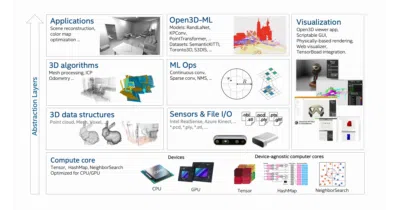
Open3D bundles 3D geometry, rendering, and machine-learning bindings into one cross-platform C++/Python library.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.