01
baidu/Unlimited-OCR
+222 ★/day↗accelerating
It wants to parse entire documents in one shot without the model getting stuck in repetitive loops.
It wants to parse entire documents in one shot without the model getting stuck in repetitive loops.
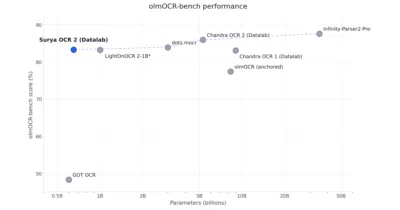
Surya exists because most OCR tools treat text, layout, and tables as separate problems; it handles all three with a single 650M-parameter vision-language model.
A NeurIPS 2022 face restoration model that treats facial features as entries in a discrete codebook, making it harder to hallucinate implausible noses.
It exists to handle the tedious wiring—annotations, dataset formats, tracking—that sits between a trained model and a useful application.
Upscayl gives desktop users a free way to enlarge and enhance low-resolution images using local Real-ESRGAN models and a Vulkan-compatible GPU.
It rounds up hundreds of AI project links so you don't have to hunt them down yourself.
OpenCV is an open-source C++ computer vision library whose own README acts as a portal rather than a product page.
MAA automates the daily chores of Arknights by treating the game screen as a computer vision problem, using OpenCV and OCR to handle farming, recruitment, and base shifts without human tapping.
Google Research releases all its code and datasets in one place, which has grown so large that the README treats a full clone as a hazard.
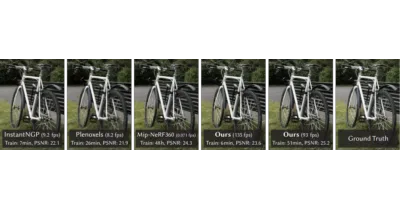
It renders high-quality novel views of real-world scenes at 30 fps by replacing costly neural radiance fields with optimized 3D Gaussians.
screenpipe continuously records your screen and audio locally so AI can search, summarize, and act on everything you’ve done without sending data to the cloud.
It bundles detection, recognition, alignment, and reconstruction into a single research-grade toolbox.
It turns face swaps and lip-syncs into queued, retryable batch jobs instead of one-off scripts.
CMU's real-time multi-person pose estimator detects body, face, hands, and feet simultaneously—body runtime stays flat even as the crowd grows.
torchvision bundles the datasets, transforms, and model architectures that every computer vision project ends up rewriting from scratch.
It exists to let developers run customized vision, text, and audio machine learning across mobile, web, and edge hardware without cloud round-trips.
Real-ESRGAN turns the ESRGAN research model into a practical tool for upscaling and restoring real-world images and videos using only synthetic training data.
It glues together CRAFT detection and CRNN recognition so you can pull text out of images without tuning neural networks yourself.
lucidrains collected two dozen ViT variants so you don't have to reimplement them from scratch.
Frigate performs real-time, local object detection on IP camera streams using OpenCV and TensorFlow, designed to integrate tightly with Home Assistant.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.