01
google/magika
+82 ★/day↗accelerating
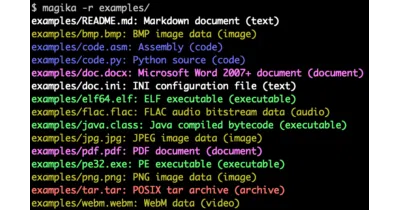
A tiny deep-learning model that guesses what a file actually contains, not just what its extension claims.
A tiny deep-learning model that guesses what a file actually contains, not just what its extension claims.
Because 'the model said so' is not an explanation, SHAP uses Shapley values from game theory to assign every feature its exact contribution to any prediction.
It centralizes model definitions so the same architecture works across PyTorch, JAX, vLLM, and llama.cpp without rewrites.
An open standard that lets you train in PyTorch and deploy on hardware that has never heard of it.
It teaches how LLMs work by implementing tokenization, attention, pretraining, and finetuning in pure PyTorch, one notebook at a time.
A readable reference for how classic machine learning actually works under the hood, from backprop to genetic algorithms.
PyTorch exists to give researchers and engineers GPU-accelerated tensor math and automatic differentiation without forcing them to leave Python’s debugger and stack traces behind.
Google's attempt to own the full machine-learning stack, from research lab to Raspberry Pi.
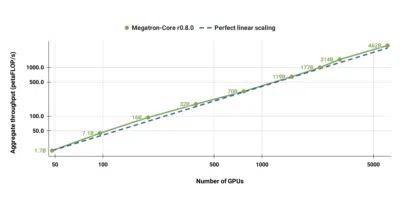
Megatron-LM splits into a reference training stack and a composable core for anyone who needs to squeeze every FLOP from a GPU cluster.
Companion notebooks for an 800-page quantitative finance textbook, from linear regression to deep reinforcement learning trading agents.
The familiar high-level API now runs on three major backends, letting you swap execution engines without rewriting model code.
TRL wraps the messy zoo of post-training algorithms into clean, scalable trainers that actually run on hardware you might already own.
Jupyter notebooks that prove you can write a GPT with little more than high-school calculus and stubbornness.
Ray treats distributed computing as a Python primitive, then layers on libraries for training, tuning, serving, and reinforcement learning.
spaCy exists to move NLP models from research notebooks into production Python without rewriting the plumbing.
nanochat is a minimal, hackable harness that lets you train and chat with a GPT-2-class LLM on a single GPU node for under $100—no hyperparameter spreadsheets required.
Because training a transformer shouldn't require 245MB of PyTorch just to multiply matrices.
NeMo shed its multimodal skin to focus on ASR, TTS, and speech LLMs—just as the field gets interesting.
A pedagogical autograd engine so small you can read it on your coffee break, yet complete enough to train a real MLP.
A volunteer-maintained Python machine learning module built on SciPy since 2007.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.