01
Niko1221/Strata
+4437 ★/day↗accelerating
A 125-billion-parameter model that normally needs a server, packed onto one gaming PC — NVIDIA card plus RAM plus SSD — writing answers faster than you can read.
A 125-billion-parameter model that normally needs a server, packed onto one gaming PC — NVIDIA card plus RAM plus SSD — writing answers faster than you can read.
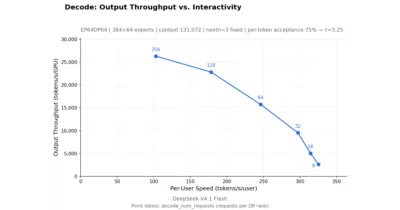
DeepInfer is the inference framework DeepSeek actually runs at scale, now released for offline use — kernels, parallelism tricks and all.
A dsh plugin that wires OpenCode's Zen gateway — free, keyless frontier models like Muse Spark 1.3 and MiMo V2.6 — straight into the harness, then spends its engineering budget on the failure modes everyone else skips.
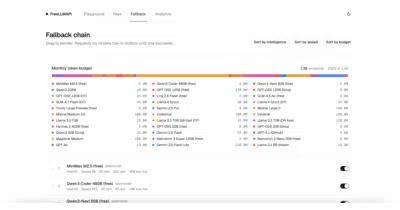
OmniRoute keeps your coding agents online by automatically failing over across 177 AI providers—including free tiers—when quotas run dry.
It aggregates the free tiers of sixteen LLM providers into one OpenAI-compatible endpoint so you can experiment without juggling rate limits.
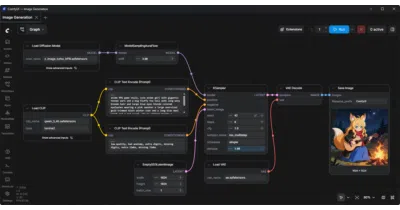
It exists because clicking 'generate' isn't enough when you need to control every model, parameter, and preprocessing step.
Pi bundles a unified LLM API, agent runtime, and interactive coding CLI into a monorepo that treats every dependency update as a potential attack.
It turns DeepSeek Harness’s command-line Web UI into a native macOS and Windows app so you can skip Node.js setup entirely.
vLLM is an open-source inference engine that pages attention key-value memory like an operating system to drive higher GPU throughput, then exposes it through an OpenAI-compatible API.
AirLLM slices giant transformers into layer shards so they fit in consumer VRAM without quantization or distillation.
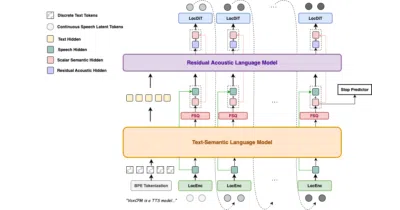
VoxCPM2 proves TTS doesn't need discrete tokens: a 2B-parameter diffusion model generates continuous 48kHz speech for 30 languages and text-prompted voice cloning.
It exists so you can download, run, and chat with open-weight LLMs locally through one CLI and REST API, keeping inference on your own silicon.
SGLang exists to push low-latency, high-throughput inference for LLMs and multimodal models from a single GPU up to massive clusters.
Open-source infrastructure for building, benchmarking, and deploying AI agents that control real macOS, Linux, and Windows desktops.
It breaks the vendor lock on Codex and Claude Code by translating their API calls to any LLM backend you choose.
It exists to run large language models on virtually any hardware—from Apple Silicon to RISC-V to your browser—with zero external dependencies and minimal setup.
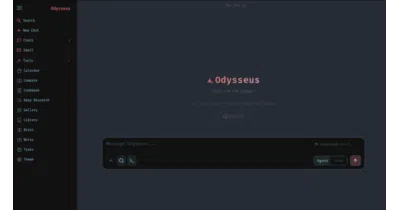
Odysseus is a self-hosted AI workspace that replicates the ChatGPT experience on your own hardware while also handling email, calendars, documents, and deep research without shipping your data to third-party clouds.
A Go proxy that handles OAuth login for Claude Code and Codex so you can call them through standard API clients.
A TTS project built to clone realistic voices from just one minute of training audio.
Because swapping from GPT-4o to Claude shouldn't require rewriting your request plumbing.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.