01
NandhaKishorM/laya
+1600 ★/day↗accelerating
Laya exists to give multilingual documents a fast, deterministic decision layer without the latency and parsing drama of autoregressive models.
Laya exists to give multilingual documents a fast, deterministic decision layer without the latency and parsing drama of autoregressive models.
It exists to train gradient-boosted trees faster and with less memory than rivals, scaling from one machine to distributed clusters.
A readable reference for how classic machine learning actually works under the hood, from backprop to genetic algorithms.
It teaches how LLMs work by implementing tokenization, attention, pretraining, and finetuning in pure PyTorch, one notebook at a time.
It exists to handle the tedious wiring—annotations, dataset formats, tracking—that sits between a trained model and a useful application.
It centralizes model definitions so the same architecture works across PyTorch, JAX, vLLM, and llama.cpp without rewrites.
A PyTorch toolkit that treats robot learning like Hugging Face treats NLP: standardized datasets, pretrained policies, and one interface for many arms.
It exists because keeping up with the training loops, quantization tricks, and inference stacks of 100+ models is a full-time job most developers would rather delegate.
torchvision bundles the datasets, transforms, and model architectures that every computer vision project ends up rewriting from scratch.
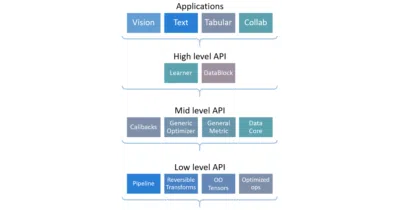
fastai wraps PyTorch in a layered API that lets beginners train classifiers in five lines and researchers rewrite the optimizer in four.
Ray treats distributed computing as a Python primitive, then layers on libraries for training, tuning, serving, and reinforcement learning.
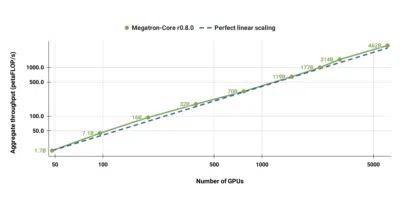
Megatron-LM splits into a reference training stack and a composable core for anyone who needs to squeeze every FLOP from a GPU cluster.
TRL wraps the messy zoo of post-training algorithms into clean, scalable trainers that actually run on hardware you might already own.
It exists to let developers run customized vision, text, and audio machine learning across mobile, web, and edge hardware without cloud round-trips.
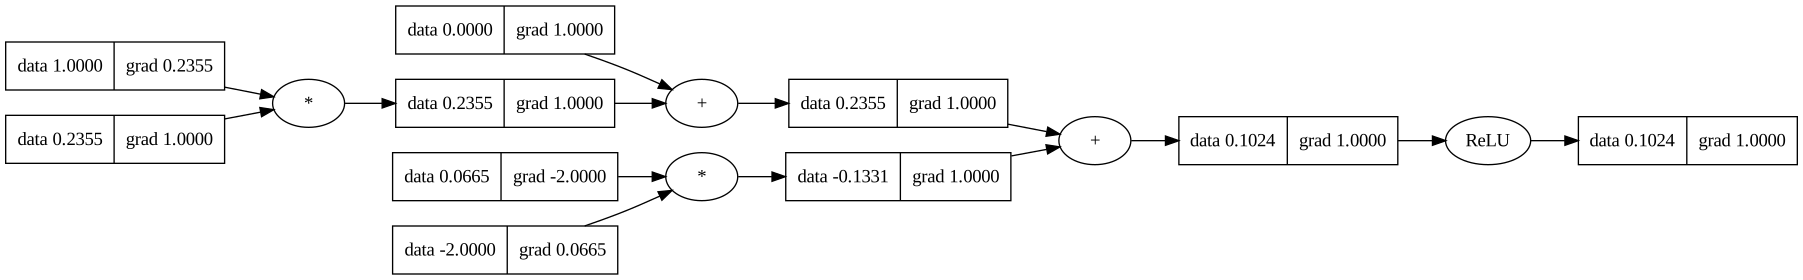
A pedagogical autograd engine so small you can read it on your coffee break, yet complete enough to train a real MLP.
A thin, opinionated layer over PyTorch that automates distributed training, mixed precision, and logging without touching your model code.
A single runtime that claims to run PyTorch, TensorFlow, and scikit-learn models faster across CPUs, GPUs, and mobile chips—without rewriting your model.
lucidrains collected two dozen ViT variants so you don't have to reimplement them from scratch.
Jupyter notebooks that prove you can write a GPT with little more than high-school calculus and stubbornness.
Ultralytics wants to stop you from stitching together separate repos for every computer vision task by bundling detection, segmentation, tracking, and pose estimation into one YOLO-backed package.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.