01
latent-spaces/brag
+1048 ★/day↗accelerating
The gap between 'it works' and 'anyone knows it works' is usually a launch video nobody wants to make — so this agent skill makes it for you.
The gap between 'it works' and 'anyone knows it works' is usually a launch video nobody wants to make — so this agent skill makes it for you.
It gives Claude Code and Codex a motion-design vocabulary—106 shot recipes, 161 previews, and a Remotion template—so they can direct cinematic product videos instead of generic slideshows.
Toonflow exists to turn a manuscript into an animated short drama without juggling five different browser tabs.
Voicebox is a local-first alternative to ElevenLabs and WisprFlow that clones voices, dictates anywhere, and gives AI agents a mouthpiece — all without shipping audio to the cloud.
It exists because clicking 'generate' isn't enough when you need to control every model, parameter, and preprocessing step.
A TTS project built to clone realistic voices from just one minute of training audio.
Wan2.2 is an open video generation suite that treats denoising timesteps like specialist jobs, scaling from a 5B model on an RTX 4090 up to a 14B MoE flagship that demands 80GB VRAM.
Pixelle-Video exists because producing a short video still requires scripting, generating assets, narrating, and editing; it automates all of that behind a single Web UI by orchestrating external AI services.
Buzz wraps OpenAI's Whisper in a cross-platform GUI that keeps your audio data local and adds features the raw model doesn't have.
It wraps Stable Diffusion—and the whole messy ecosystem of models, upscalers, and LoRAs—into one browser-based workbench.
A minimal C/C++ port of OpenAI’s Whisper built to transcribe speech locally on phones, browsers, and underclocked POWER9 boxes.
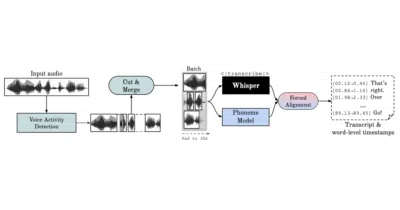
OpenAI's Whisper is accurate but slow and timestamp-imprecise; WhisperX bolts on batching, forced phoneme alignment, and speaker diarization to fix that.
A reimplementation of OpenAI's Whisper that trades the original inference engine for CTranslate2 and gains up to 4× speed without sacrificing accuracy.
SGLang exists to push low-latency, high-throughput inference for LLMs and multimodal models from a single GPU up to massive clusters.
An open-source toolkit that turns casual selfies into compliant ID photos using offline AI matting and face detection.
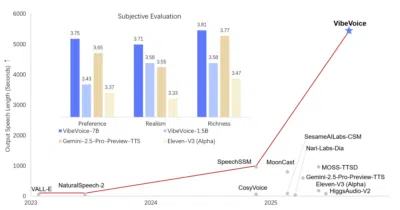
VibeVoice is a family of open-source speech models from Microsoft built to ingest, transcribe, and generate very long audio sessions—up to an hour—in a single pass.
It turns a single sentence into a complete short drama by chaining LLMs, image generators, video models, and FFmpeg into one automated pipeline.
A Chinese speech toolkit that bundles ASR, diarization, emotion detection, and streaming into one MIT-licensed package.
It gives artists and professionals a local, node-based studio for Stable Diffusion, treating AI as a collaborator rather than an opaque generator.
It automates video transcription, translation, and dubbing while stubbornly insisting on single-line, human-readable subtitles.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.