01
UncensoredLabs/uncensored-ai-api
+97% /wk +120 ★/day→steady
UncensoredLabs packages refusal-stripped DeepSeek and GLM models behind a drop-in base-URL swap — the repo itself is docs and sample code, not the service.
UncensoredLabs packages refusal-stripped DeepSeek and GLM models behind a drop-in base-URL swap — the repo itself is docs and sample code, not the service.
A Rust-based Chinese IME that treats your daily typing as a language lesson, because opening a study app is a chore.
Project Maya runs GLM-5.3-Flash privately on one to sixteen GPUs by keeping hot experts in VRAM, warm ones in RAM, and the rest on NVMe.
AnyJev turns any open LLM into a calibrated decision engine—typed choices with probabilities you can threshold—without touching a single model weight.
It turns 150+ scattered LLM guides into a single engineering curriculum—from API basics to production Agents and ByteDance interviews—because hoarding bookmarks is not a learning strategy.
An experimental Qwen3.5-4B language model with a 32-bit RISC-V CPU compiled directly into its transformer weights, using the model's Gated DeltaNet state as RAM.
MemT-1.0 bakes persistent memory into the model itself, so history lives in a fixed-size latent state instead of a growing KV cache.
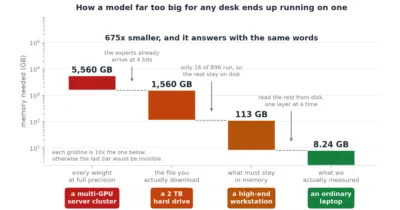
To prove that a 2.78-trillion-parameter model can run on a single CPU with 8 GB of RAM and no GPU.
It replaces autoregressive LLM classification with a single parallel forward pass, cutting latency from seconds to sub-20 ms while staying local.
It rewrites every kernel for AMD Strix Halo and a single 179B-parameter MoE family to beat general-purpose engines without spending fewer bits.
MASCOT is a training framework that keeps multi-agent LLM companions in distinct personas while a director agent prevents them from collapsing into an echo chamber.
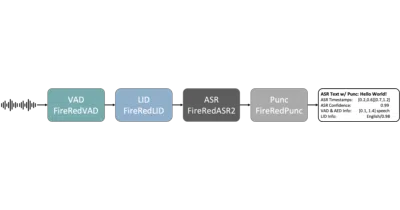
FireRedASR2S bundles ASR, voice detection, language ID, and punctuation into a single pipeline optimized for Mandarin, 20+ regional variants, English code-switching, and even singing.
It unifies Stable Diffusion, GGUF chat, Whisper, and Kokoro TTS into a single offline desktop GUI so you can skip cloud APIs, subscriptions, and censorship filters.
Most LLM inference stacks treat consumer AMD GPUs as second-class citizens; hipfire targets the full RDNA family with a single Rust binary that keeps Python out of the hot path.
RedKnot accelerates long-context inference by sorting attention heads into four species—global, local, retrieval, and dense—then giving each its own KV reuse strategy and sparsity rules, built as an SGLang extension.
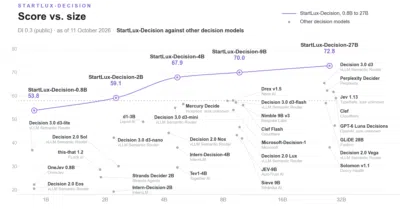
StartLux-Decision treats decisions as classification, not chat: one forward pass, a calibrated probability per option, and reasoning only when confidence dips below a gate.
This repo is a surgical stack of vLLM patches, requantization scripts, and speculative decoders built to squeeze Qwen3.8-27B — and up to 268k tokens of context — into a single 24 GB consumer GPU.
Laya runs in Node.js via ONNX Runtime, turning tickets and emails into calibrated choices, rubric scores, and P(true) values in a single forward pass.
A curated, source-backed catalog of 155 projects built on Jev, a model that answers typed questions with probabilities instead of generating text.
A curated awesome-list tracking 167 papers, models, benchmarks, and independent evaluations around TypeSafe's System One decision models.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.