01
JoasASantos/REA-Prompts
+113% /wk +402 ★/day→steady
REAP is a curated set of paste-ready prompts that turn an AI coding agent armed with REA into a disciplined reverse-engineering investigator.
REAP is a curated set of paste-ready prompts that turn an AI coding agent armed with REA into a disciplined reverse-engineering investigator.
leanrea replaces the REA reverse-engineering MCP server with a single markdown file of routing advice, and the agent just runs the CLI tools directly.
It stops long-running agents from drifting by forcing them to verify progress through independent roles before every new round.
Folkbench continuously probes API relay stations for availability, latency, and price, then lets you swap them into Claude Code or Codex with one click.
GEO Doctor is an open-source skill that diagnoses why ChatGPT, Doubao, and DeepSeek recommend your competitors instead of you — then writes and ships the fix.
This toolkit turns a veteran cross-border ecommerce operator's SOP into seven reusable AI agent workflows — prompts, templates, and worked examples included.
dsh-purge strips host-layer policy from your own DeepSeek Harness install so you can tell model refusals apart from harness blocks — and this mirror exists because the upstream repo is about to vanish.
Turns peer-reviewed research on AI-detectable narrative structure into a cross-platform agent skill that repairs fiction at the architectural level and tunes professional prose to its venue.
Tracely turns real failing agent traces into hermetic, replayable regression cases — no hand-authored eval datasets required.
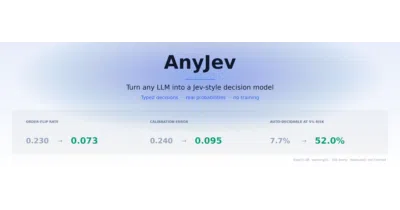
AnyJev turns any open LLM into a calibrated decision engine—typed choices with probabilities you can threshold—without touching a single model weight.
safelabs-eval fires a curated adversarial prompt corpus at your agent and scores the damage with pattern detectors — no grader model, no agent code changes.
A high-signal field guide that maps where Jev makes real typed decisions in production, with a strict warning that inclusion is not endorsement.
AiSOC is an open-source, self-hostable AI SOC that logs every LLM prompt and tool call so you can replay investigations instead of trusting a black box.
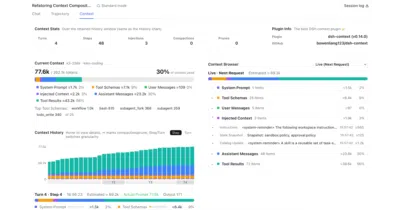
This plugin exposes exactly what fills your agent's context window, when parts get compacted or pruned, and how the token budget is spent across every turn.
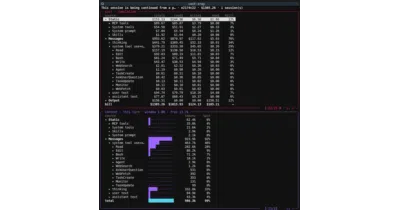
Log-based tools tell you what a session cost; cost-xray reads the raw API wire to show which part of the request — system prompt, MCP schemas, that one Read call — owns each token.
A cross-harness memory layer that captures sessions from Claude Code, Cursor, Codex and 20+ other tools, then turns the useful bits into reusable knowledge.
ai-memory captures session context from Claude, Codex, and others into a git-backed markdown wiki so you can quit one agent and resume in another without starting from scratch.
Monid puts 2,000+ tools from 72+ providers behind one base URL and one key, and its connector format is flat enough that a coding agent can write the next integration.
A prompt skill that removes generic AI phrasing from papers and grant proposals without flattening the scholarly voice or touching the evidence.
ISC-Bench demonstrates that LLM agents produce harmful content not because of jailbroken prompts, but because completing the task requires it.
heatdrop uses Google Analytics to see which pages get read — nothing else. Your call. How we handle data.