nace-ai/kapitsa
A local inference engine that treats your Mac like it means it
Kapitsa squeezes Qwen, Nemotron and Flint models onto Apple Silicon fast enough to run real coding agents — including a 180B model on a 48 GB Mac.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
Kapitsa is a C++ inference engine for Apple Silicon Macs (M1 or newer, macOS 14+) that runs Qwen, Nemotron, Clover, Flint and Drex models locally. It exposes OpenAI- and Anthropic-compatible APIs (/v1/chat/completions, /v1/messages, /v1/responses) with streaming, tool calls and JSON-schema output, and can launch Claude Code, Codex, opencode, aider, Goose and friends straight onto a local model. It also ships a model catalog with per-RAM-size precision picks, from a 4B up to a 180B MoE.
The interesting bit
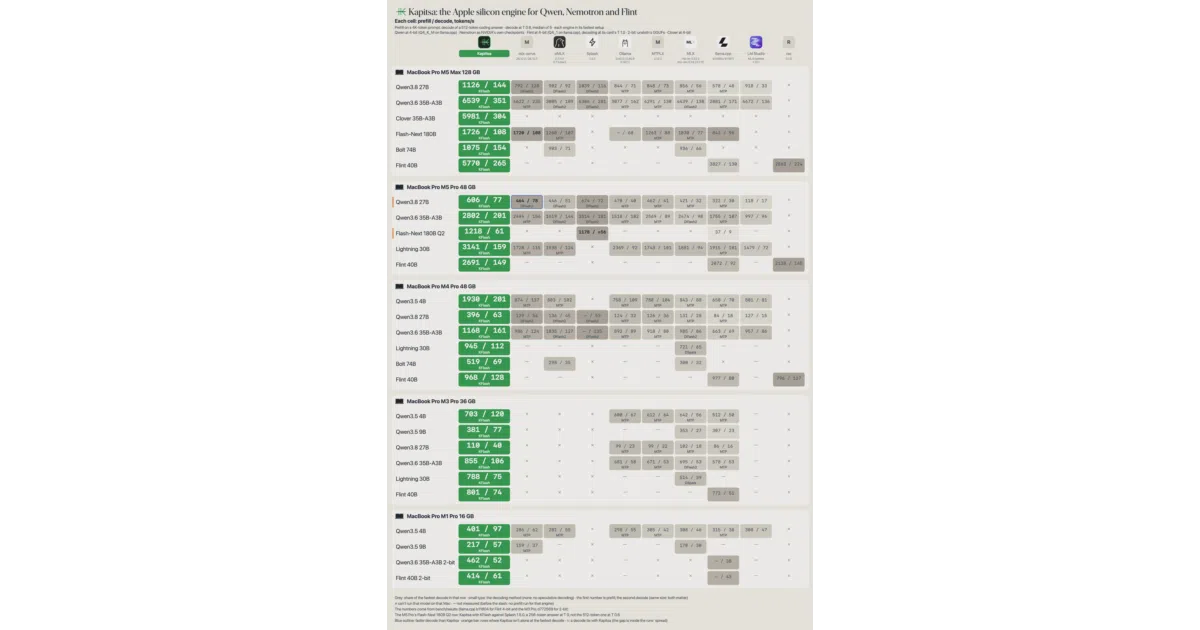
The headline trick is KFlash: tree speculative decoding where one verify pass checks a whole tree of the drafter’s guesses, with a dedicated drafter model behind each supported model. Add to that prefill split across the GPU and the Neural Engine, and routed experts streamed from SSD so a 180B model fits a 48 GB Mac at 61 tok/s. Disk-cached conversations mean a 16K follow-up after a restart starts in 0.16 s instead of 17 s.
Key highlights
- 351 tok/s decode on Qwen3.6 35B-A3B on an M5 Max; fastest decode in 33 of 38 model/Mac pairs measured against nine engines
- 180B Qwen3.8-Flash-Next runs on a 48 GB Mac by streaming experts from SSD
- One command starts a coding agent on a local model; APIs stay OpenAI/Anthropic-compatible
- Multi-Mac clustering: a Mac that can’t hold a model forwards to one that can, or
--splitspreads layers across the network kapitsa bench --submitfeeds a community leaderboard;bench compareranks every engine you have installed- Opt-in C ABI SDK (plus a Node.js binding) for reusing a loaded model in-process
Caveats
- Apple Silicon only — no Linux or Windows, so this is a Mac-only party
- Several models are text-only (Flint, four Nemotrons, the 35B’s
16gbbuild); image support varies by model - The benchmarks are self-published, though the methodology, raw runs and a comparison tool are provided so you can verify on your own hardware
Verdict
If you run coding agents on a Mac and want them on local models without giving up speed, this is squarely aimed at you. Everyone on Linux, Windows, or non-agent workloads can keep walking.
Frequently asked
- What is nace-ai/kapitsa?
- Kapitsa squeezes Qwen, Nemotron and Flint models onto Apple Silicon fast enough to run real coding agents — including a 180B model on a 48 GB Mac.
- Is kapitsa open source?
- Yes — nace-ai/kapitsa is open source, released under the Apache-2.0 license.
- What language is kapitsa written in?
- nace-ai/kapitsa is primarily written in C++.
- How popular is kapitsa?
- nace-ai/kapitsa has 713 stars on GitHub.
- Where can I find kapitsa?
- nace-ai/kapitsa is on GitHub at https://github.com/nace-ai/kapitsa.