XHToken/Spark-X2.6
The 4B model that out-agents models twice its size
Spark-X2.5 is a pair of open-weight models (4B and 1.7B) trained with agents in mind — tool use, coding, browsing — plus a hybrid attention design that makes a native 1M-token context affordable on-device.
Velocity · 7d
+21
★ / day
Trend
↗accelerating
star history
What it does Spark-X2.5 is an open-weight model series from XHToken: a 4B and a 1.7B general-purpose LLM covering conversation, writing, translation, reasoning, coding, tool use, and agentic workflows across 200+ languages. The GitHub repo itself is the release hub — model cards, benchmark tables, and download pointers — while the weights live on Hugging Face, ModelScope, Ollama, and several regional mirrors, with FP8 and INT8 quantized versions available.
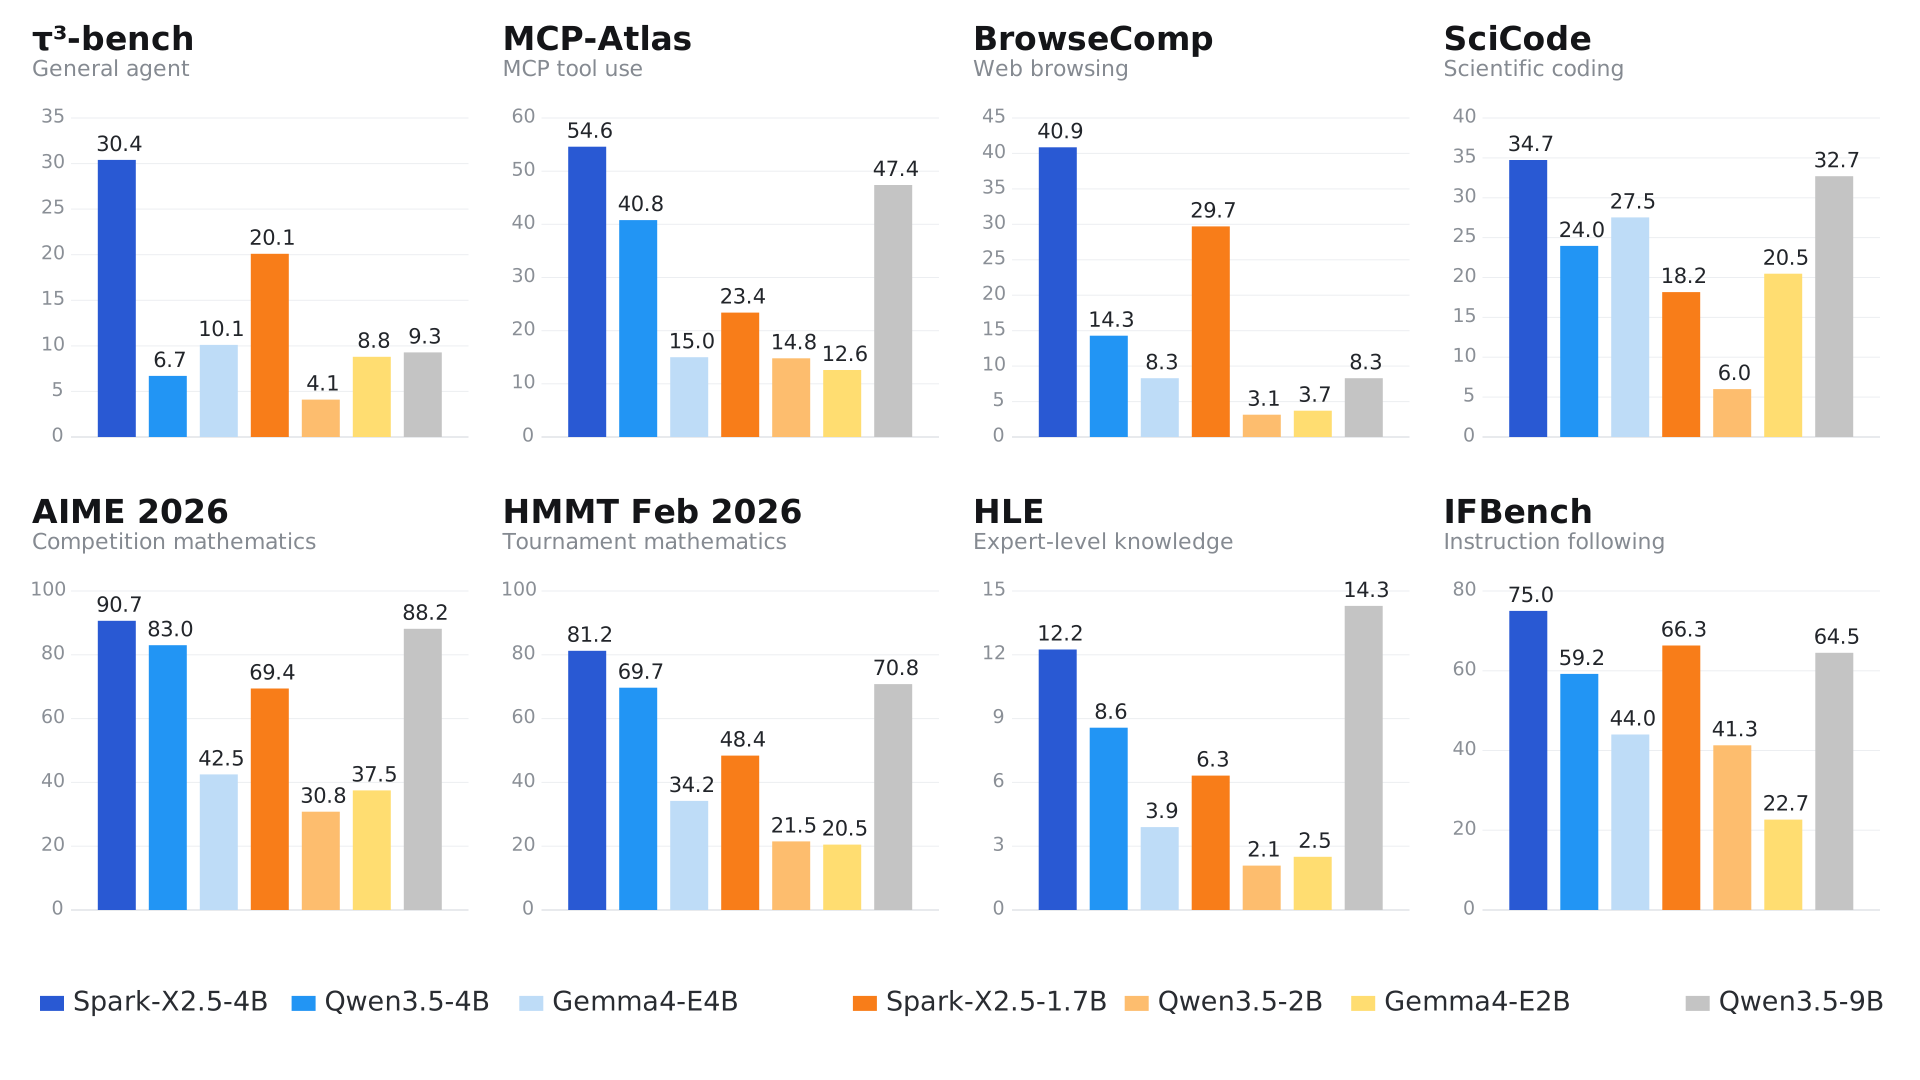
The interesting bit The architecture is the hook: one full-attention layer for every three sliding-window layers, which keeps long-context compute in check while natively supporting up to 1M tokens. The training bet is agentic — the 4B scores 30.4 on τ³-bench where Qwen3.5-9B manages 9.3, and 40.9 on BrowseComp against 8.3. Training ran on Huawei Ascend clusters with large-scale RL plus a post-training technique the README names MOPD but never explains.
Key highlights
- Hybrid attention (1 full + 3 sliding-window layers) delivers a native 1M-token window without the usual long-context compute tax
- Agent-first results: leads same-size and larger models on τ³-bench, MCP-Atlas, BrowseComp, SWE-Bench Pro, and Workspace Bench
- Runs in vLLM, SGLang, llama.cpp, and MLX; deployable through Ollama, LM Studio, and the PocketPal AI app on iOS and Android
- Hardware reach beyond NVIDIA — Huawei Ascend and Hygon support — with fine-tuning via LLaMA-Factory
- Integrated with agent harnesses including Codex, Claude Code, OpenClaw, and Hermes
Caveats
- This is a model-card repo, not code: no source, no training scripts — the deliverable is weights hosted elsewhere
- The benchmark table is the vendor’s own, and it is not a clean sweep — the 4B trails Qwen3.5-9B on SWE-Bench Verified (41.6 vs 53.1) and on τ²-bench
- MOPD, the headline post-training technique, gets a name and nothing more
Verdict Worth a look if you run local agents on modest hardware, especially outside the NVIDIA bubble. Skip it if you came for a repo to read — the code here is a README, and the substance is in the weights.
Frequently asked
- What is XHToken/Spark-X2.6?
- Spark-X2.5 is a pair of open-weight models (4B and 1.7B) trained with agents in mind — tool use, coding, browsing — plus a hybrid attention design that makes a native 1M-token context affordable on-device.
- Is Spark-X2.6 open source?
- Yes — XHToken/Spark-X2.6 is open source, released under the Apache-2.0 license.
- How popular is Spark-X2.6?
- XHToken/Spark-X2.6 has 827 stars on GitHub and is currently accelerating.
- Where can I find Spark-X2.6?
- XHToken/Spark-X2.6 is on GitHub at https://github.com/XHToken/Spark-X2.6.