OpenBMB/MiniCPM-OCR
An OCR model that tells you when it's wrong
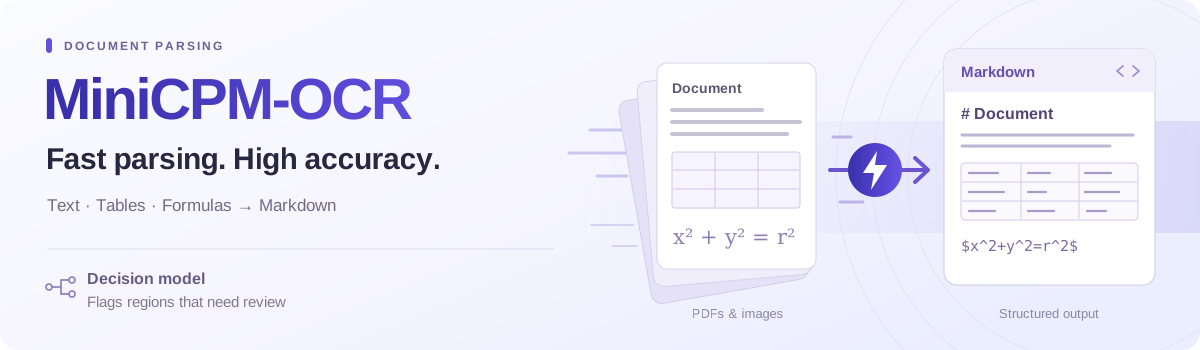
MiniCPM-OCR pairs a fast 1.3B document parser with a second model that scores its own output, so you know which regions to trust.
Too new to rank. Velocity needs a few days of history.
not enough history yet
star history
What it does
MiniCPM-OCR 1.0 is a 1.3B vision-language model from the MiniCPM-V family that parses Chinese and English documents and PDFs into text, tables, formulas, and Markdown — including messy inputs like scans, photos, curved pages, and recaptured documents. It also handles key information extraction and runs on-device on iOS, Android, and HarmonyOS, fully offline. The repo ships a pip SDK, a Docker image, a self-hostable web demo, and day-one support for vLLM, SGLang, llama.cpp, and Ollama.
The interesting bit
The companion model, MiniCPM-OCR Jev, is a 2B “correctness decision” model: given an image and its OCR output, it returns a 0–1 quality score per region, flagging what needs human review. It works with other parsing models too, not just its sibling. A 2B judge scoring AUROC 93.6 on JevOCRBench, beating a 35B model and nearly matching a 397B one, is the quiet flex here.
Key highlights
- Claims 93.68 on Real5-OmniDocBench and leading scores on OmniDocBench v1.6, Wild-OmniDocBench, and olmOCR-Bench among open-source OCR models
- DSpark decoding acceleration improves end-to-end efficiency by 55%; throughput cited as ~1.49× PaddleOCR-VL-1.6 and ~3.62× MinerU2.5 Pro
- 54.7 on OCRBench v2 for general recognition
- Markdown output preserves text found in image regions and links to cropped images
- Supports further fine-tuning; quantized variants and multiple chip platforms at release
Caveats
- The vLLM, SGLang, llama.cpp, and Ollama support is pinned to specific source revisions, some on unmerged branches — not necessarily in stable releases
- Benchmark figures are the project’s own; a reproduction guide is provided but we haven’t verified the numbers
- The radar chart itself notes some comparison values “remain to be confirmed”
Verdict
Worth a look if you’re building document pipelines and want confidence scores instead of blind trust in OCR output. If you need languages beyond Chinese and English, this isn’t your model yet.
Frequently asked
- What is OpenBMB/MiniCPM-OCR?
- MiniCPM-OCR pairs a fast 1.3B document parser with a second model that scores its own output, so you know which regions to trust.
- Is MiniCPM-OCR open source?
- Yes — OpenBMB/MiniCPM-OCR is open source, released under the Apache-2.0 license.
- What language is MiniCPM-OCR written in?
- OpenBMB/MiniCPM-OCR is primarily written in TypeScript.
- How popular is MiniCPM-OCR?
- OpenBMB/MiniCPM-OCR has 1k stars on GitHub.
- Where can I find MiniCPM-OCR?
- OpenBMB/MiniCPM-OCR is on GitHub at https://github.com/OpenBMB/MiniCPM-OCR.