rdi-berkeley/agents-last-exam
Berkeley grades AI agents on the artifacts they leave behind
Because puppeteering an agent step by step strips away what makes it capable, ALE hands it real work and grades only the result.
Not currently ranked — collecting fresh signals.
star history
What it does
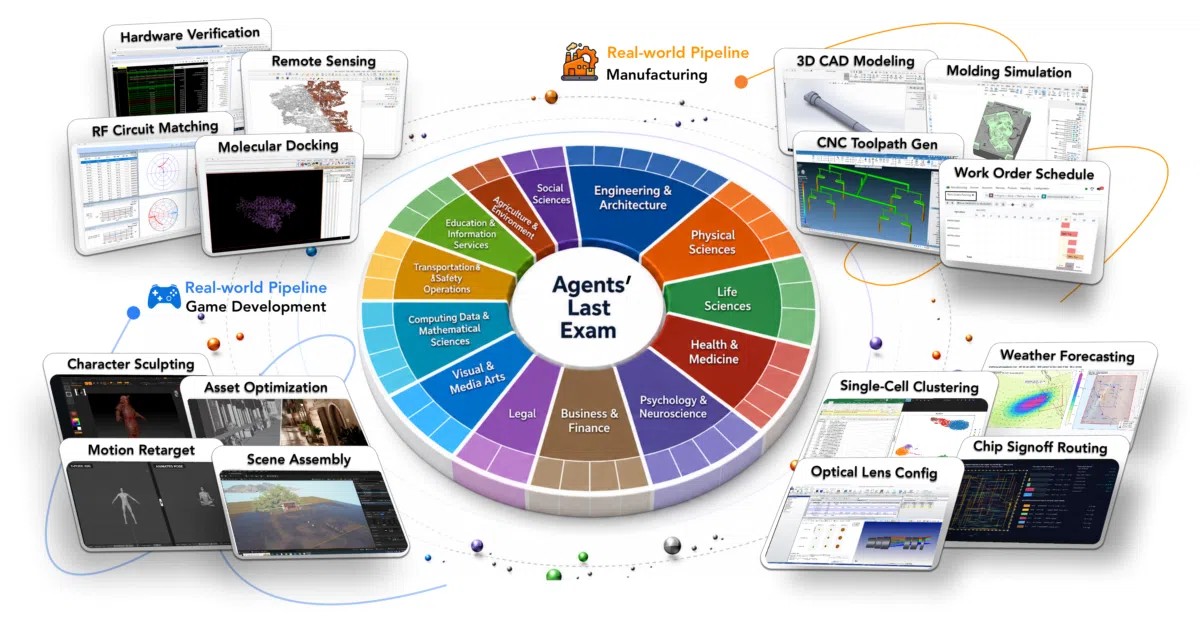
Agents’ Last Exam (ALE) is an open evaluation framework for frontier agents — a harness driving a foundation model through its own action loop, tools, and memory. Each experiment pairs one agent, one sandbox (a genuine Windows or Linux machine stocked with real professional software and data), and one task written as an executable main.py. The agent receives only the task description, works to completion, and a grader (evaluate()) scores the output against a hidden reference on a 0–1 scale. The repo ships the ale_run orchestrator, roughly 150 public tasks spanning 55 subdomains, and reference integrations for several harnesses.
The interesting bit The hidden reference is staged only after the agent finishes, so the answer key physically cannot leak into the run — the exam metaphor is load-bearing. Equally clever: most harnesses are CLI-native, but real jobs need a screen too, so ALE lifts any of them to desktop competence via a cross-OS CUA MCP bridge that exposes screenshot, click, and type as ordinary tools in the agent’s loop.
Key highlights
- 55 subdomains across 13 industry clusters, mapped to the U.S. O*NET/SOC 2018 occupational taxonomy and built with hundreds of industry experts
- Sandboxes run on Google Cloud, AWS, Alibaba Cloud, QEMU/KVM, local Docker containers, or a machine you already operate
- Every run yields a uniform trajectory — each step, tool call, and observation in one schema — plus raw logs and artifacts, replayable end to end
- Curated task lists in three difficulty tiers: near-term, full-spectrum, last-exam
- New harnesses plug in by implementing a small deployer; ALE-Claw is the reference agent
Caveats
- The local Docker profile covers only a lighter Ubuntu subset — full task coverage assumes VMs, with Google Cloud as the recommended production path
- QEMU/KVM support is CPU-only
- The ~150 public tasks are the open slice; licensed and provider-specific task subsets sit outside the repo
Verdict Worth a close look if you build agent harnesses and want an end-to-end score on work that resembles actual jobs. If you just want a leaderboard number, the live site serves that without the sandbox plumbing.
Frequently asked
- What is rdi-berkeley/agents-last-exam?
- Because puppeteering an agent step by step strips away what makes it capable, ALE hands it real work and grades only the result.
- Is agents-last-exam open source?
- Yes — rdi-berkeley/agents-last-exam is open source, released under the Apache-2.0 license.
- What language is agents-last-exam written in?
- rdi-berkeley/agents-last-exam is primarily written in Python.
- How popular is agents-last-exam?
- rdi-berkeley/agents-last-exam has 1.1k stars on GitHub.
- Where can I find agents-last-exam?
- rdi-berkeley/agents-last-exam is on GitHub at https://github.com/rdi-berkeley/agents-last-exam.