open-compass/VLMEvalKit
One command to evaluate 220+ vision-language models
VLMEvalKit exists so researchers stop rewriting evaluation scripts for every new vision-language benchmark.
Not currently ranked — collecting fresh signals.
star history
What it does
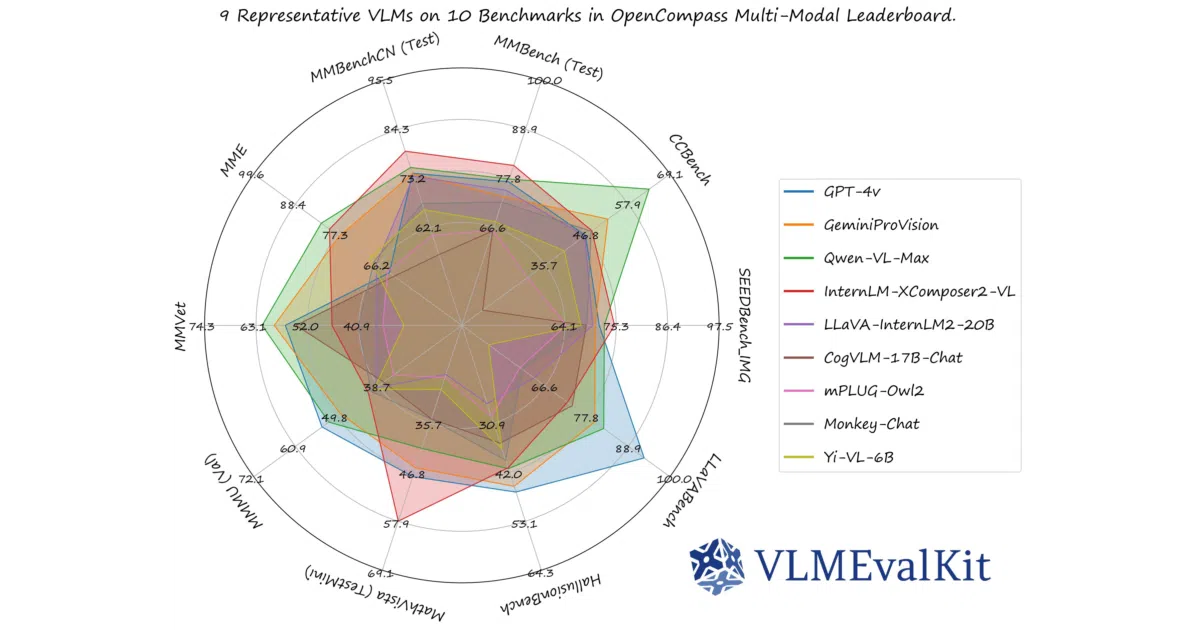
VLMEvalKit is an open-source Python toolkit for evaluating large vision-language and multi-modal models. It bundles support for over 220 models and 80 benchmarks into one framework, letting researchers run evaluations with a single command instead of juggling dozens of repositories. To add a new model, you only implement a generate_inner() method; the toolkit handles data downloading, inference, and metrics using generation-based evaluation with exact matching or LLM-based answer extraction.
The interesting bit The maintainers are refreshingly honest about the tool’s limits: it does not promise to replicate the exact accuracy numbers from every third-party benchmark’s original paper, because it standardizes all models under one generation-based pipeline. Recent updates also tackle practical headaches rarely mentioned in academic code, like splitting `` tags from reasoning models and switching to TSV output to dodge Excel’s 32,767-character cell limit on long responses.
Key highlights
- Supports 220+ LMMs, from commercial APIs to open-source weights
- Covers 80+ image and video benchmarks, including Video-MME-v2 and PhyX
- Distributed inference via LMDeploy or VLLM for faster large-scale evaluation
- Standardized generation-based evaluation with exact-match and LLM-based extraction
- Integrated OpenVLM leaderboards with fully downloadable result sets
Caveats
- Exact accuracy numbers from original benchmark papers may differ because VLMEvalKit unifies everything under its own generation-based protocol
- Dependency requirements are fragmented; different models demand specific
transformersversions ranging from 4.33.0 to 5.2.0+ - Long model responses can exceed Excel’s cell limits, so TSV output is strongly recommended for thinking-mode or verbose models
Verdict Researchers building or comparing vision-language models will save weeks of boilerplate. If your goal is to reproduce a specific paper’s original evaluation protocol down to the decimal, the maintainers explicitly warn that this is not the tool for that job.
Frequently asked
- What is open-compass/VLMEvalKit?
- VLMEvalKit exists so researchers stop rewriting evaluation scripts for every new vision-language benchmark.
- Is VLMEvalKit open source?
- Yes — open-compass/VLMEvalKit is open source, released under the Apache-2.0 license.
- What language is VLMEvalKit written in?
- open-compass/VLMEvalKit is primarily written in Python.
- How popular is VLMEvalKit?
- open-compass/VLMEvalKit has 4.5k stars on GitHub.
- Where can I find VLMEvalKit?
- open-compass/VLMEvalKit is on GitHub at https://github.com/open-compass/VLMEvalKit.