omnimind-ai/OmniInfer
One Rust binary, every llama.cpp flavor your laptop can hold
OmniInfer wraps a zoo of local inference backends behind a single CLI, TUI, and mobile-embeddable API layer.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
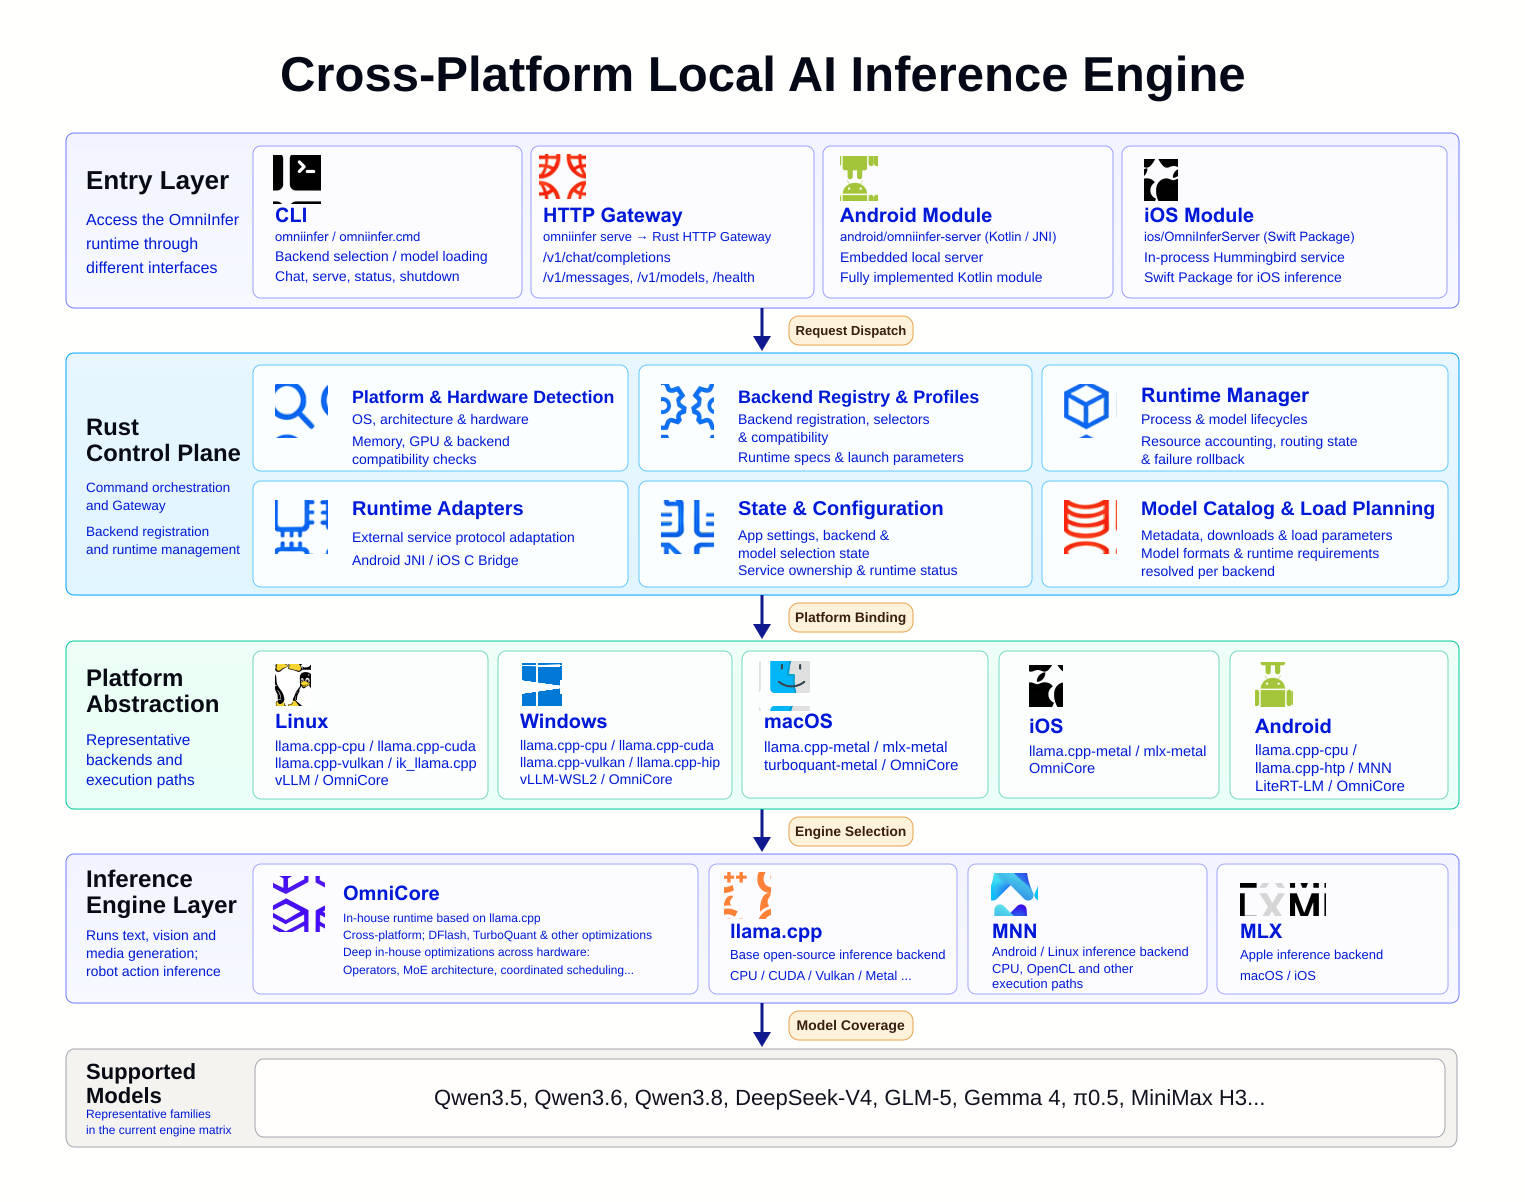
OmniInfer is a cross-platform inference engine, written in Rust, for running LLMs and vision-language models entirely on your own hardware. It hides the usual ceremony — model compilation, hardware adaptation, backend selection — behind a terminal UI that recommends a compatible engine, installs a prebuilt runtime, and loads a local model. It also ships an omniinfer serve mode exposing OpenAI- and Anthropic-compatible HTTP endpoints, so existing clients can point at localhost and pretend it’s the cloud.
The interesting bit
The real trick is backend abstraction: llama.cpp, MLX, MNN, ik_llama.cpp, LiteRT-LM, ExecuTorch QNN, stable-diffusion.cpp, and more sit behind one control plane, with the engine picked per device. The same codebase spans desktop CLI, HTTP gateway, an Android Gradle module, and an iOS Swift package — plus an optional browser dashboard demo running a SmolVLA robot policy in the LIBERO simulator, which is not your typical LLM chat README.
Key highlights
- Fully local, private inference — no cloud round-trips
- OpenAI- and Anthropic-compatible local APIs
- Multi-backend switching with hardware-aware selection
- Fine-grained control over context length, GPU offload, and KV cache
- Day-0 support for new models (e.g. Qwen3.8-27B) by tracking upstream llama.cpp
Caveats
- Runtime availability varies by platform and accelerator; Windows users need WSL2 for vLLM
- Bleeding-edge model support sometimes requires a source-built backend until prebuilts catch up
- It’s largely orchestration glue over existing engines — the value is the unification, not a new inference kernel
Verdict
Worth a look if you juggle multiple local runtimes or want one embeddable inference layer across desktop and mobile. Skip it if you’re happy with your single llama.cpp build and nothing else.
Frequently asked
- What is omnimind-ai/OmniInfer?
- OmniInfer wraps a zoo of local inference backends behind a single CLI, TUI, and mobile-embeddable API layer.
- Is OmniInfer open source?
- Yes — omnimind-ai/OmniInfer is open source, released under the Apache-2.0 license.
- What language is OmniInfer written in?
- omnimind-ai/OmniInfer is primarily written in Rust.
- How popular is OmniInfer?
- omnimind-ai/OmniInfer has 1.7k stars on GitHub.
- Where can I find OmniInfer?
- omnimind-ai/OmniInfer is on GitHub at https://github.com/omnimind-ai/OmniInfer.