jesdga95/basalt
A Blackwell-only inference engine that swaps VRAM for system RAM
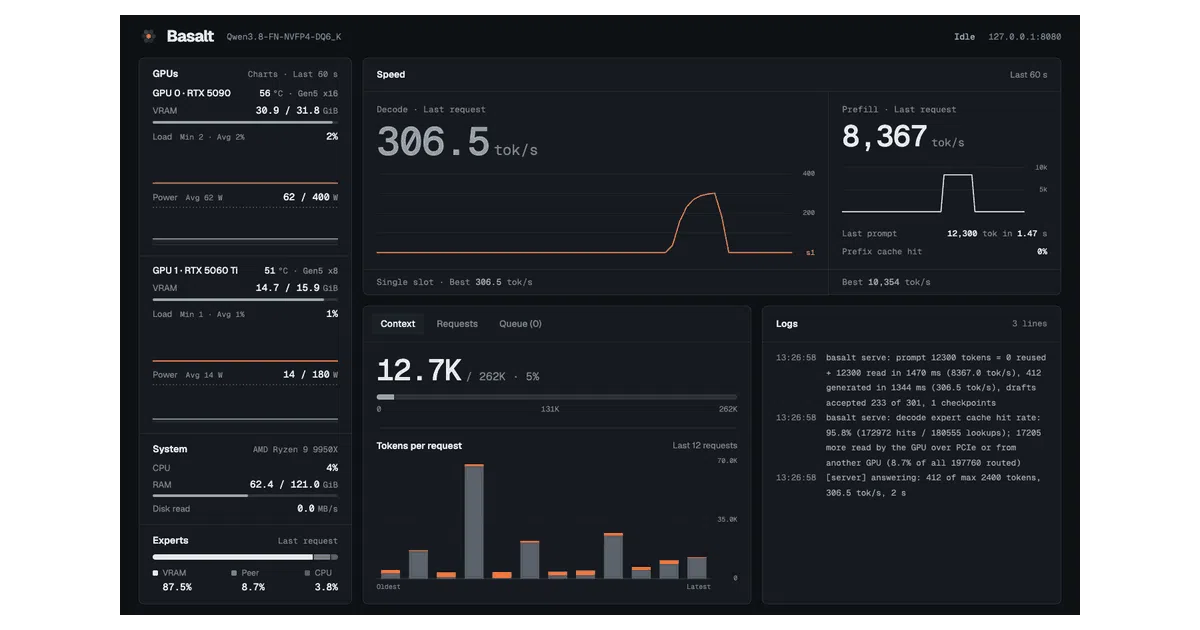
Basalt runs three specific LLMs locally on NVIDIA's newest GPUs, spilling MoE experts into system memory when VRAM runs short.
Too new to rank. Velocity needs a few days of history.
not enough history yet
star history
What it does
Basalt is a local inference server for exactly three models — Qwen3.8-Flash-Next, DeepSeek-V4.1-Flash, and Qwen3.8-27B — on NVIDIA Blackwell GPUs (sm_120), Linux or Windows. When a mixture-of-experts model doesn’t fit in VRAM, the experts live in system RAM instead. It exposes both the OpenAI and Anthropic APIs, so existing clients just work, and handles images, PDFs, and (for two of the three models) video.
The interesting bit
The scope discipline is the story: rather than being a general engine, it’s tuned for one GPU architecture and three models, with per-model speculative drafting (MTP, DSpark, DFlash 2) on by default. The README is also candid about lineage — it’s a fork of Strata with kernels adapted from Infernix and ideas from llama.cpp, not a from-scratch CUDA opus.
Key highlights
- MoE experts spill from VRAM into system RAM, with a
resident-expertsoption to pin hot ones - Context up to 1,048,576 tokens on DeepSeek-V4.1-Flash; 262,144 on the Qwen models
- Speaks both OpenAI and Anthropic API dialects on localhost
- Ships prebuilt Linux and Windows release archives
- Ships its own
.basaltmodel file format with a documented changelog
Caveats
- Hard hardware floor: Blackwell (compute capability 12.0) with CUDA 13 — nothing older qualifies
- Model support is a closed set of three; if you want Llama or Mistral, this isn’t your engine
- The README asks for donated Blackwell compute for testing, which hints at limited test coverage
Verdict
If you own a Blackwell card and want one of these three models running locally with big context and API compatibility, this is a focused, honest tool. Everyone else — pre-Blackwell GPU or different model tastes — should stick with llama.cpp.
Frequently asked
- What is jesdga95/basalt?
- Basalt runs three specific LLMs locally on NVIDIA's newest GPUs, spilling MoE experts into system memory when VRAM runs short.
- Is basalt open source?
- Yes — jesdga95/basalt is open source, released under the MIT license.
- What language is basalt written in?
- jesdga95/basalt is primarily written in C++.
- How popular is basalt?
- jesdga95/basalt has 1.7k stars on GitHub.
- Where can I find basalt?
- jesdga95/basalt is on GitHub at https://github.com/jesdga95/basalt.