eagle-hq/EAGLE-4
Speculative decoding that doesn't collapse under load
EAGLE-4 is a drafter plus harness that tunes its own speculation depth to your batch size, hardware, and workload — so you can leave it on in production.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
EAGLE-4 is the fourth round of the EAGLE speculative-decoding family: a small draft model guesses tokens ahead, the target model verifies them, and generation gets faster without changing the output. The repo ships eagle-harness, a package that plugs EAGLE-4 into SGLang, vLLM, and TokenSpeed. Point your engine at an EAGLE-4 draft model and it serves with speculation on.
The interesting bit
Most speculative decoding is tuned for one sweet spot — usually single-request latency — and turns into a liability once the batch grows. eagle-harness instead measures the actual costs on your setup and decides how far to speculate per request, so the draft tree fits the batch size and hardware. The README claims it keeps pace with plain decoding up to 512 concurrent requests on the high-load recipe.
Key highlights
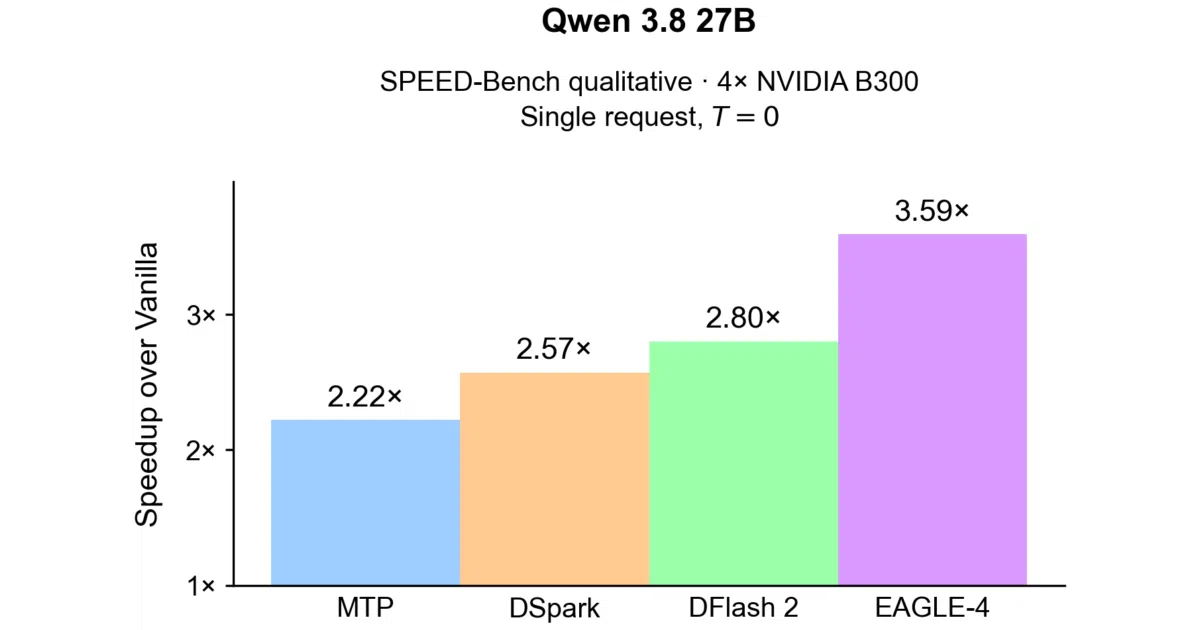
- Up to 3.4× faster generation on Qwen3.8-27B, with output identical to the target model’s own
- Measured speedups: SGLang 3.42× (1 request) down to 1.39× (64 concurrent) on 4× B300; vLLM and TokenSpeed in the same ballpark
- Works on AMD too — 2.07× at 8 concurrent requests on a single MI355X
- Output correctness is checked in the support matrix, not just asserted
- Docker images, calibration docs, and per-engine guides with the exact measured recipes
Caveats
- Source-available, not OSI open source: commercial use is capped at a US $20M revenue threshold, and competing offerings need a separate license — read the fine print before shipping this at work
- The headline numbers are B300 hardware; your mileage on older GPUs is unmeasured here
- Pip installs need the CUDA toolkit and a C++ compiler, and the quick start pulls about 62 GB of weights
Verdict
Worth a look if you serve an LLM and want speculation that survives real traffic instead of demo conditions. Skip it if your license team flinches at source-available terms with revenue thresholds.
Frequently asked
- What is eagle-hq/EAGLE-4?
- EAGLE-4 is a drafter plus harness that tunes its own speculation depth to your batch size, hardware, and workload — so you can leave it on in production.
- Is EAGLE-4 open source?
- Yes — eagle-hq/EAGLE-4 is an open-source project tracked on heatdrop.
- What language is EAGLE-4 written in?
- eagle-hq/EAGLE-4 is primarily written in Python.
- How popular is EAGLE-4?
- eagle-hq/EAGLE-4 has 1k stars on GitHub.
- Where can I find EAGLE-4?
- eagle-hq/EAGLE-4 is on GitHub at https://github.com/eagle-hq/EAGLE-4.