StayLameBro/backburner
Your iPhone is the extra GPU your Mac LLM was missing
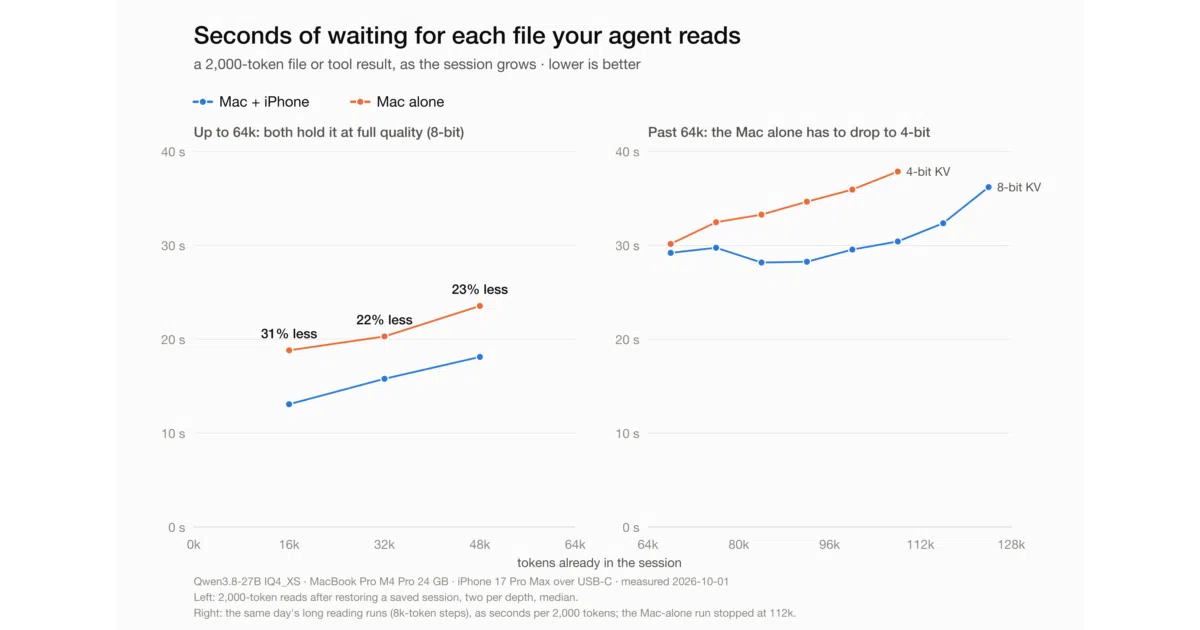
Backburner turns a USB-C-tethered iPhone into a second inference device, cutting agent prefill times 29-44% and extending context to ~200k tokens.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
Backburner is a llama.cpp fork that splits a 27B model (Qwen3.8-27B) across a Mac and a tethered iPhone. During prefill, the Mac runs layers 1-40 and streams the residual to the phone, which runs layers 41-64 on its GPU while the Mac starts the next batch. Past 64k context, the phone changes jobs: it holds the oldest KV pages and computes attention over them, so a 24 GB Mac can carry 8-bit context out to 196k-229k tokens instead of dropping to 4-bit at 64k.
The interesting bit
The phone’s Neural Engine gets used in a genuinely odd way: since old keys never change, each 16k-key page is compiled into an ANE model with the keys baked in as weights. That plus the GPU cuts old-key attention from 279 to 176 ms per token at 140k. Also notable: greedy output is token-identical with and without the phone — this is a speed and memory play, not an accuracy tradeoff.
Key highlights
- 29-44% faster prefill at 16k-48k context on a 24 GB M4 Pro + iPhone 17 Pro Max
- Context sized from the phone’s free memory at startup; tested end-to-end to 128k at 8-bit
- Mac-side wins too: SME2 CPU co-compute, Metal fusions, DFlash2 speculative decoding (25 vs 11.3 tok/s decode vs stock llama.cpp)
- SSD prompt cache restores a 27k-token session start in 0.3-5 s
- Community-verified on 8 GB Macs, iPads, and older iPhones (with varying results)
Caveats
- Reads under ~512 tokens stay entirely on the Mac; small agent steps don’t benefit
- iPhone 16 Pro Max reportedly runs hot over long prefills; non-Pro iPhones’ USB 2 ports are too slow for split prefill
- Some reported setups are still being debugged (128k on iPhone 18 Pro Max, occasional unexplained iPad failures)
Verdict
If you run local models on Apple hardware and own a Pro iPhone, this is one of the more creative uses of that cable in your drawer. If you’re on Linux/Android or expect it to fix decode speed below 64k, wait for the roadmap.
Frequently asked
- What is StayLameBro/backburner?
- Backburner turns a USB-C-tethered iPhone into a second inference device, cutting agent prefill times 29-44% and extending context to ~200k tokens.
- Is backburner open source?
- Yes — StayLameBro/backburner is open source, released under the MIT license.
- What language is backburner written in?
- StayLameBro/backburner is primarily written in Python.
- How popular is backburner?
- StayLameBro/backburner has 1k stars on GitHub.
- Where can I find backburner?
- StayLameBro/backburner is on GitHub at https://github.com/StayLameBro/backburner.