RunanywhereAI/trnrt
One Trainium box, 3.57M tokens a minute, and the kernels to prove it
TrnRT is an open inference engine that serves GLM-5.3-Flash with 1M-token context from a single trn2.48xlarge, using hand-written NKI megakernels for decode.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does TrnRT serves an OpenAI-compatible API (chat, completions, streaming, tool calls, reasoning output) from one AWS Trainium2 instance. Right now it supports exactly one model — GLM-5.3-Flash, a 320B-parameter MoE with 18B active, FP8, and a 1M-token context — though the engine, router, caches, and compile pipeline are built to carry more families. Two engines run per box, each tensor-parallel over 32 logical NeuronCores, behind a session-affine router that keeps a conversation pinned to one engine’s prefix cache.
The interesting bit Decode runs as NKI megakernels — roughly one fused kernel per layer half, covering KDA attention, the fused DSA layer, mHC, and the MoE FFN. The reasoning is refreshingly concrete: decode here isn’t memory-bandwidth-bound, it’s bound by small instructions, kernel boundaries, and exposed collectives, so the kernels keep the working set in SBUF, use both physical cores symmetrically, and fold the collectives inside the kernel. The 1M-token context comes from sparse attention (top 2,048) plus linear attention with fixed-size state, so the KV footprint doesn’t grow with history.
Key highlights
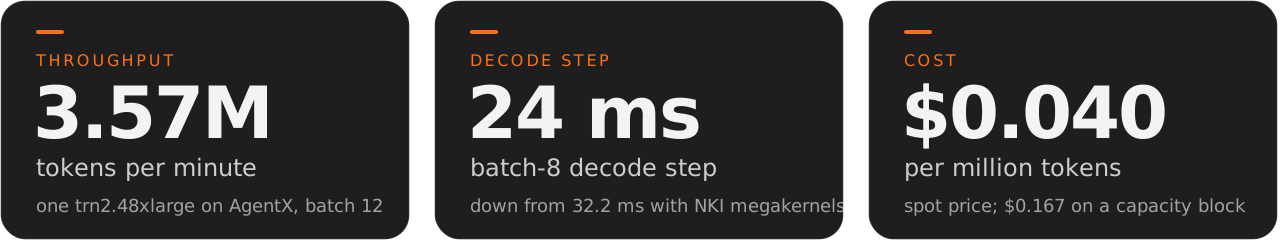
- AgentX benchmark: 3.57M tokens/min at batch 12 on one box — $0.040 per million tokens at spot pricing ($0.167 on a capacity block).
- Prefix cache is a radix tree over FP8 KV pages, with a host-memory tier for evicted pages and state checkpoints.
- Offline compile: graphs are built on any x86_64 CPU host; the serving box loads them and compiles nothing by default.
- The repo’s current build is verified against the benchmarked build — byte-identical outputs on 384 of 384 requests, graph equivalence on all 157 graphs across 32 ranks.
- CPU test suite runs without a NeuronCore, so you can develop without renting the farm.
Caveats
- One model, one instance type (
trn2.48xlarge), pinned to Neuron SDK 2.32 and Python 3.13. If you’re not already in the Trainium ecosystem, this is a narrow door. - The compile cache takes hours to build, and the benchmark numbers come from an earlier build (the repo verifies equivalence against it rather than re-running AgentX).
Verdict If you have Trainium capacity and want an open, inspectable serving stack that treats NeuronCores as something worth writing kernels for, this is a serious piece of work. If you’re on GPUs or need model variety today, wait for the “coming soon” list to lengthen.
Frequently asked
- What is RunanywhereAI/trnrt?
- TrnRT is an open inference engine that serves GLM-5.3-Flash with 1M-token context from a single trn2.48xlarge, using hand-written NKI megakernels for decode.
- Is trnrt open source?
- Yes — RunanywhereAI/trnrt is open source, released under the Apache-2.0 license.
- What language is trnrt written in?
- RunanywhereAI/trnrt is primarily written in Python.
- How popular is trnrt?
- RunanywhereAI/trnrt has 1.3k stars on GitHub.
- Where can I find trnrt?
- RunanywhereAI/trnrt is on GitHub at https://github.com/RunanywhereAI/trnrt.