QwenAudio/Fun-Audio-Chat
An 8B audio LLM that thinks at 5Hz and speaks at 25Hz
Built for fluid voice conversations, this 8B-parameter model roughly halves GPU hours by processing speech at two resolutions instead of one.
Collecting fresh signals — velocity needs a few days of history.
collecting data…
star history
What it does
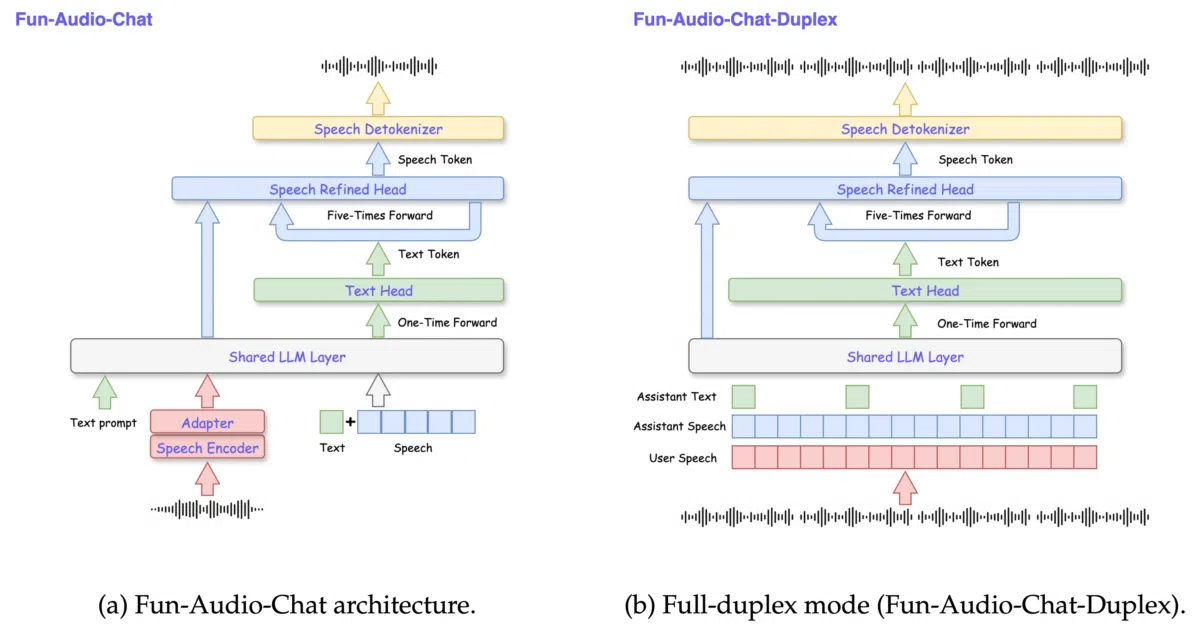
Fun-Audio-Chat is an 8B-parameter large audio language model from Alibaba Cloud that handles end-to-end spoken dialogue. It accepts speech input and generates either text or speech output, covering question answering, audio understanding, function calling, and even voice empathy. The model is designed to run as a conversational agent rather than a simple transcriber or command parser.
The interesting bit
Instead of processing everything at a single high frame rate, it splits speech encoding into a 5Hz shared backbone and a 25Hz refined head. The README claims this dual-resolution approach nearly halves GPU hours compared with conventional single-rate models while preserving output quality. A related paper, DrVoice, was accepted at ICLR 2026.
Key highlights
- Dual-Resolution Speech Representations: a 5Hz backbone plus 25Hz refinement head, which the authors say cuts training compute by roughly half versus 12.5Hz or 25Hz monolithic encoders.
- Benchmark coverage: ranks among top ~8B models on OpenAudioBench, VoiceBench, UltraEval-Audio, MMAU/MMAU-Pro, MMSU, Speech-ACEBench, Speech-BFCL, and VStyle.
- Supports both speech-to-text and speech-to-speech inference, with a third-party vLLM integration reportedly yielding ~20× speedup on short audio and ~50× on long audio.
- Bundles a web demo and training scripts built atop LlamaFactory, Moshi, and CosyVoice.
- Apache 2.0 license.
Caveats
- Inference requires about 24 GB of GPU memory, and training demands four 80 GB GPUs, so this is not a hobbyist laptop project.
- The README lists many benchmark names but does not show raw scores or confidence intervals, so “top-tier” is the project’s own framing.
- It relies on a separate 0.5B CosyVoice model for speech synthesis, meaning the full pipeline is not contained in a single checkpoint.
Verdict
Worth a look if you are building voice assistants or researching efficient audio LLM architectures. Skip it if you need a lightweight edge model or a drop-in replacement for a text-only chatbot.
Frequently asked
- What is QwenAudio/Fun-Audio-Chat?
- Built for fluid voice conversations, this 8B-parameter model roughly halves GPU hours by processing speech at two resolutions instead of one.
- Is Fun-Audio-Chat open source?
- Yes — QwenAudio/Fun-Audio-Chat is open source, released under the Apache-2.0 license.
- What language is Fun-Audio-Chat written in?
- QwenAudio/Fun-Audio-Chat is primarily written in Python.
- How popular is Fun-Audio-Chat?
- QwenAudio/Fun-Audio-Chat has 1k stars on GitHub.
- Where can I find Fun-Audio-Chat?
- QwenAudio/Fun-Audio-Chat is on GitHub at https://github.com/QwenAudio/Fun-Audio-Chat.