Anil-matcha/open-genjutsu · 14 Nov 2026 · Feature
The Decision Engine Disguised as an Awesome List
Rajiv Menon
Staff Writer
A repo named open-genjutsu turns out to be a disciplined field guide to Jev, TypeSafe's model for typed judgments — in a namespace where 'Genjutsu' usually means video character swaps.
Anil-matcha/open-genjutsu
★1.2k stars Velocity · 7d +9.6 ★/day ↘cooling
star history
The naming is the first thing you notice. Anil-matcha/open-genjutsu sits in a corner of GitHub where “Genjutsu” — the Naruto-derived word for illusion techniques — has become shorthand for a very specific thing: AI video tools that keep the motion of a source clip while replacing everything else. Higgsfield sells a proprietary product by that exact name, and at least two open-source clones (D3voz/openjutsu and abdullayevziyodulla/open-genjutsu) reproduce the trick locally with open weights and bring-your-own API keys.
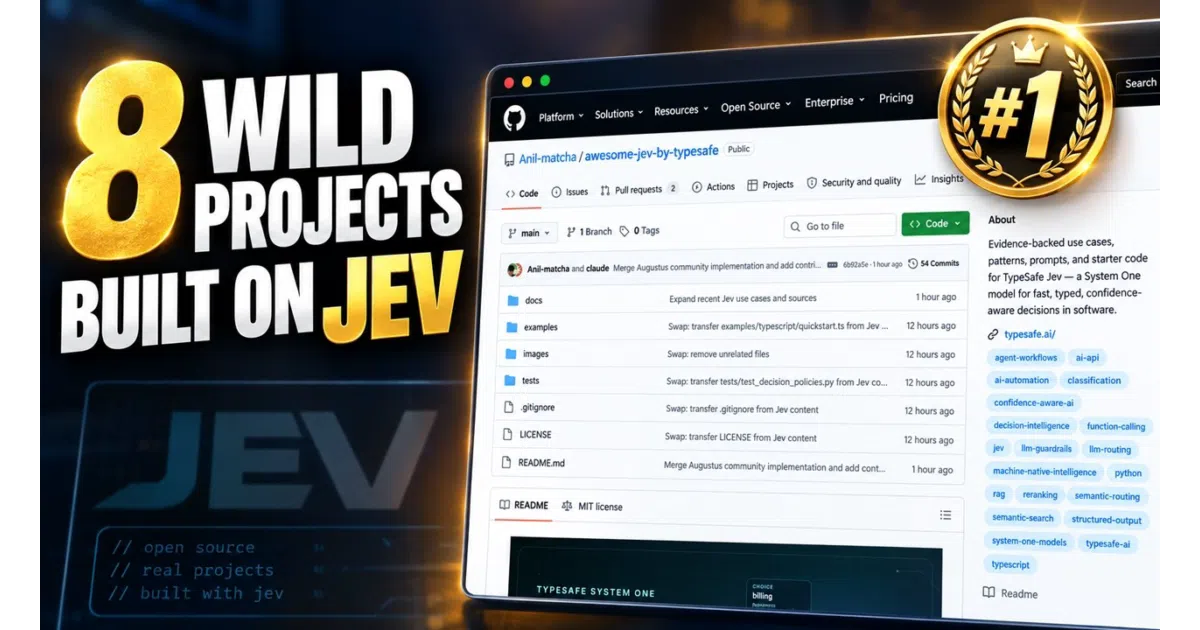
Open this particular repo, though, and the README is something else entirely: “Awesome Jev,” an evidence-backed catalog of use cases, patterns, and community implementations for Jev — TypeSafe AI’s first “System One Model.” No video, no character swaps, no illusions. Just a model that answers questions instead of writing paragraphs. The name collision is unfortunate and genuinely confusing for discovery, but the content inside is worth the disorientation, because it documents one of the more interesting bets in the current model landscape: that the future of LLM-adjacent infrastructure isn’t generation at all — it’s judgment.
What Jev is, and why the boring part is the point
The core contract, as the README puts it, is deceptively simple: text or JSON state goes in, typed questions go in, constrained answers with probabilities come out. Your code keeps the control flow, the thresholds, and the side effects.
That last clause is the whole thesis. Most language models produce strings for people — prose, code, replies. Jev instead evaluates a state against questions whose answer spaces you define in advance. It offers three primitives. A Choice picks one value from a known, finite set — which department owns this ticket, which function to dispatch. A Score places something on an ordered rubric you define — how frustrated is this customer, how severe is this incident. A Noul returns the probability that a statement is true — does this passage answer the question, is this prompt a jailbreak attempt. Choice and Score also return full probability distributions and a confidence value, which means the caller gets two axes per decision: what the model believes, and how surely.
This positions Jev in what the README calls the “fuzzy middle between brittle rules and expensive generative workflows.” Rules engines are deterministic but shatter on ambiguity. Generative LLMs handle ambiguity but return free-form text that some other component has to parse, validate, and trust. The typed-decision model is a third category: semantic judgment with a machine-checkable output contract. The design rule the README repeats like a mantra — questions describe judgments; code owns composition, thresholds, and side effects — is essentially a software-engineering argument dressed up as a model pitch. That’s a compliment. It’s the part most model launches get wrong.
Why the hype spiked
The attention around Jev, as reflected in this collection, has three visible drivers.
First, the economics. The README’s quick-facts table lists Jev at $0.042 per million input tokens with output tokens listed as free, alongside documented limits of 250,000 tokens per second and 1,200 requests per minute. Whether those numbers hold under real production load is anyone’s guess — the README itself says limits can change dynamically — but the pricing shape signals intent: this is meant to be called constantly, inside loops, per passage, per candidate, per tick.
Second, the latency claims. TypeSafe’s launch materials report 70–500 millisecond end-to-end response times and describe Jev as roughly two orders of magnitude faster and more efficient for System One-shaped tasks. The README is unusually honest about these being vendor-reported, workload-dependent numbers that you should benchmark yourself — a rare flash of restraint in an AI market where vendor benchmarks are usually quoted as scripture.
Third, and most tellingly, the ecosystem explosion. The README catalogs dozens of independent implementations that appeared almost immediately: a project where Jev plays Snake by choosing one legal move per tick while code generates the action set; an MCP server giving coding agents typed claim-verification and content-screening tools; a Home Assistant integration exposing Noul, Choice, and Score answers as automation entities; a Rust pre-commit gate that screens staged diffs for secrets; a PostgreSQL extension for asking typed semantic questions over table data; an experimental sub-second trading loop that ships dry-run by default; a MuJoCo quadrotor control loop with Jev in the decision path. There are calibration toolkits that fit per-question confidence thresholds on labeled data and write lock files, a Korean-language benchmark, and at least two open reproductions attempting Jev-style parallel decisions on local infrastructure.
When strangers build drone controllers and git hooks around your API within weeks of launch, you’ve hit a nerve. The nerve, arguably, is that a huge class of production AI work — routing, triage, guardrails, re-ranking, moderation — never wanted a chatbot in the first place. It wanted a fast, cheap, calibrated judge.
What the repository actually is
It’s worth being clear about what this repo is: curation, not code. It’s an awesome-list — a README, some example files, offline tests, and a contribution process. There’s no engine here, no weights, no novel research. As software, it’s glue at best. Its value is entirely editorial, and that editorial work is better than most.
The list enforces evidence discipline that most awesome-lists don’t. Every use case carries a source link. Vendor-reported results are explicitly separated from community measurements. The quick-facts table is pinned to a snapshot date — September 19, 2026 — with a disclaimer that prices, limits, and aliases can shift. The contribution guidelines require disclosure of affiliation, links to the specific files that call the API, no unverified performance claims, and explicit marking of experimental or dry-run-only paths. The “what Jev is not” section is almost as long as the pitch: not a chatbot, not a guarantee of correctness, not a replacement for authorization or human review, text-only for now.
The use-case map itself — thirty-one numbered workflows plus an industry table — reads less like a marketing artifact and more like a pattern language. Support triage via speculative fan-out (ask every likely-needed question in one call, ignore the irrelevant answers). Confidence-gated routing where reversible read-only actions get low thresholds and irreversible ones get high thresholds. Extraction cascades where a small generative model proposes fields, Jev Nouls verify whether each value is actually supported by the source, and only failures escalate to an expensive reasoning model. RAG passage filtering where relevance, contradiction, and prompt-injection risk are scored per passage before anything reaches the answering model. These are reference architectures, and their common shape — deterministic skeleton, semantic judgment at the joints — is the actual intellectual content of the collection.
The Genjutsu next door
The naming confusion isn’t trivial, because the real Genjutsu ecosystem is having its own moment. Higgsfield’s Genjutsu is a commercial video tool that preserves motion, camera work, and timing while replacing characters, wardrobe, sets, and props from reference images — with a cheaper Lite variant launched for short clips. The open-source responses are instructive: D3voz/openjutsu runs entirely on local GPU with open weights (MiniMax H3 for generation, SAM 3.1 for tracking, Qwen3-VL for shot description), while abdullayevziyodulla/open-genjutsu is a local MIT-licensed studio that restores the full source soundtrack and routes generation through the user’s own paid provider accounts.
Around them orbits a crowded commercial field: Magic Hour’s character replace, DomoAI’s body swap, Viggle’s physics-aware JST-1-based swaps, and general AI editors from Adobe, invideo, and Canva. None of it has anything to do with typed decision models. Someone searching for an open Genjutsu could land on this repo and reasonably feel baited; someone searching for Jev patterns might never find it. (Two community sources gathered alongside this piece — a Reddit discussion thread and a character-swap page — were inaccessible behind security blocks, so independent chatter about either ecosystem couldn’t be verified here.)
Limits, caveats, and open questions
The README’s own caveats deserve amplification rather than paraphrase. Jev is English-primary, with explicit guidance to test non-English workloads before relying on calibrated thresholds — a real constraint for the global use cases the industry table cheerfully lists. It’s text-only; no images, audio, or video. It was early-access at launch. Model aliases can silently move between versions, and the collection’s advice to pin versioned IDs and log the returned version in every response is the kind of hard-won operational wisdom that usually only appears after someone’s thresholds quietly broke.
The deeper open question is calibration itself. The README is careful to note that calibration describes groups of predictions, not any individual answer — a Noul near 0.5 means the question is uncertain, not that the answer is “medium.” That honesty matters, because the entire confidence-gated architecture (act on high confidence, review on uncertainty) only works if the probabilities mean what they claim. The community’s response — dedicated calibration-fitting tools, benchmark harnesses with committed datasets, an open reproduction or two — suggests people are testing that assumption rather than taking it on faith. That’s the right instinct, and the collection’s insistence that every benchmark record include the versioned model ID, question definitions, dataset, and baseline is the right standard.
Where this heads is unclear in the interesting way. If Jev’s calibration holds across domains, the decision-layer pattern — cheap judge in front of, behind, and beside expensive generators — becomes standard plumbing, and lists like this one become the de facto documentation of a new architectural idiom. If it doesn’t hold, the whole edifice reduces to a very fast classifier with good manners. Either way, the repo captures a genuine inflection point: the moment the industry started asking models not to write, but to decide — and started building the guardrails, drones, git hooks, and Postgres extensions to prove it.
Sources
- D3voz/openjutsu: One-click character swap for videos: an ...
- AI Video Editor | Online Video Editing
- Free AI Character Swap Video - Replace Characters Online
- Higgsfield Genjutsu — Reality Manipulation for Video
- Free AI Video Editor: Edit Videos with AI
- AI Character Swap & Body Swap for Video
- Meet Higgsfield Genjutsu: How It Works and What You Get
- AI Video Editor - Create & Edit Videos with AI
- Free AI Body Swap — Full Character Replacement in Video
- abdullayevziyodulla/open-genjutsu: Local MIT-licensed ...
- Anybody using AI Video editing? which tool do you ...
- AI Character Swap: Replace Characters in Videos Instantly